MongoDB
Airbyte's certified MongoDB connector offers the following features:
- Change Data Capture (CDC) using MongoDB change streams, read directly with the MongoDB driver.
- Full refresh and incremental sync modes for every collection.
- Reliable replication of collections of any size with checkpointing: an interrupted sync resumes from the last document it checkpointed instead of starting over.
- A choice between a discovered schema (fields sampled from your documents) and a schemaless mode that syncs each document as one JSON object.
This connector's Docker image was renamed from airbyte/source-mongodb-v2 to airbyte/source-mongodb in version 3.0.0; the connector definition is unchanged.
This page covers setup (Quick Start), how replication works, and reference information (data type mapping, configuration parameters and changelog). If you are upgrading from version 2.x, read the migration guide first.
Quick Start
Setting up a MongoDB source takes four steps:
- Create a dedicated read-only MongoDB user.
- Find the connection string of your replica set or sharded cluster, hosted on MongoDB Atlas or self-hosted.
- Create the MongoDB source in Airbyte.
- Allow inbound traffic from Airbyte if your cluster restricts incoming connections.
Requirements
- A replica set or a sharded cluster (connected through
mongos). A standalonemongodhas no oplog and therefore no change streams: Full Refresh works against it, but an Incremental sync fails when the change stream is opened. A single-node replica set is fine for development: see Convert a Standalone to a Replica Set. - MongoDB 4.4 or later. The connector is tested against MongoDB 7.0. Deletes carry the deleted document only on MongoDB 6.0 or later with pre-images enabled on the collection.
- On MongoDB Atlas, a dedicated cluster (M10 tier or above). Shared tiers (M0, M2, M5) do not support the operations the connector relies on and may fail during connection setup.
- An oplog large enough to cover the gap between two syncs, with margin. See MongoDB Oplog and Change Streams.
Step 1: Create a dedicated read-only MongoDB user
These steps create a dedicated, read-only user for replicating data. You can also use an existing MongoDB user, as long as it has the privileges described below. A dedicated user makes the connector's activity easy to tell apart in your logs and lets you revoke access without affecting anything else.
The privileges the connector needs depend on how many databases you configure:
| Databases configured | Required privileges |
|---|---|
| One | The built-in read role on that database. The change stream is opened on the database itself, so no cluster-wide privilege is needed. |
| Several | readAnyDatabase (on Atlas: the Only read any database built-in role). Changes from several databases are read through one cluster-wide change stream, which requires read privileges on every database. |
Either way, read access is all the connector needs: it never writes to your cluster and never reads the local or config databases.
MongoDB Atlas
-
Log in to the MongoDB Atlas dashboard.
-
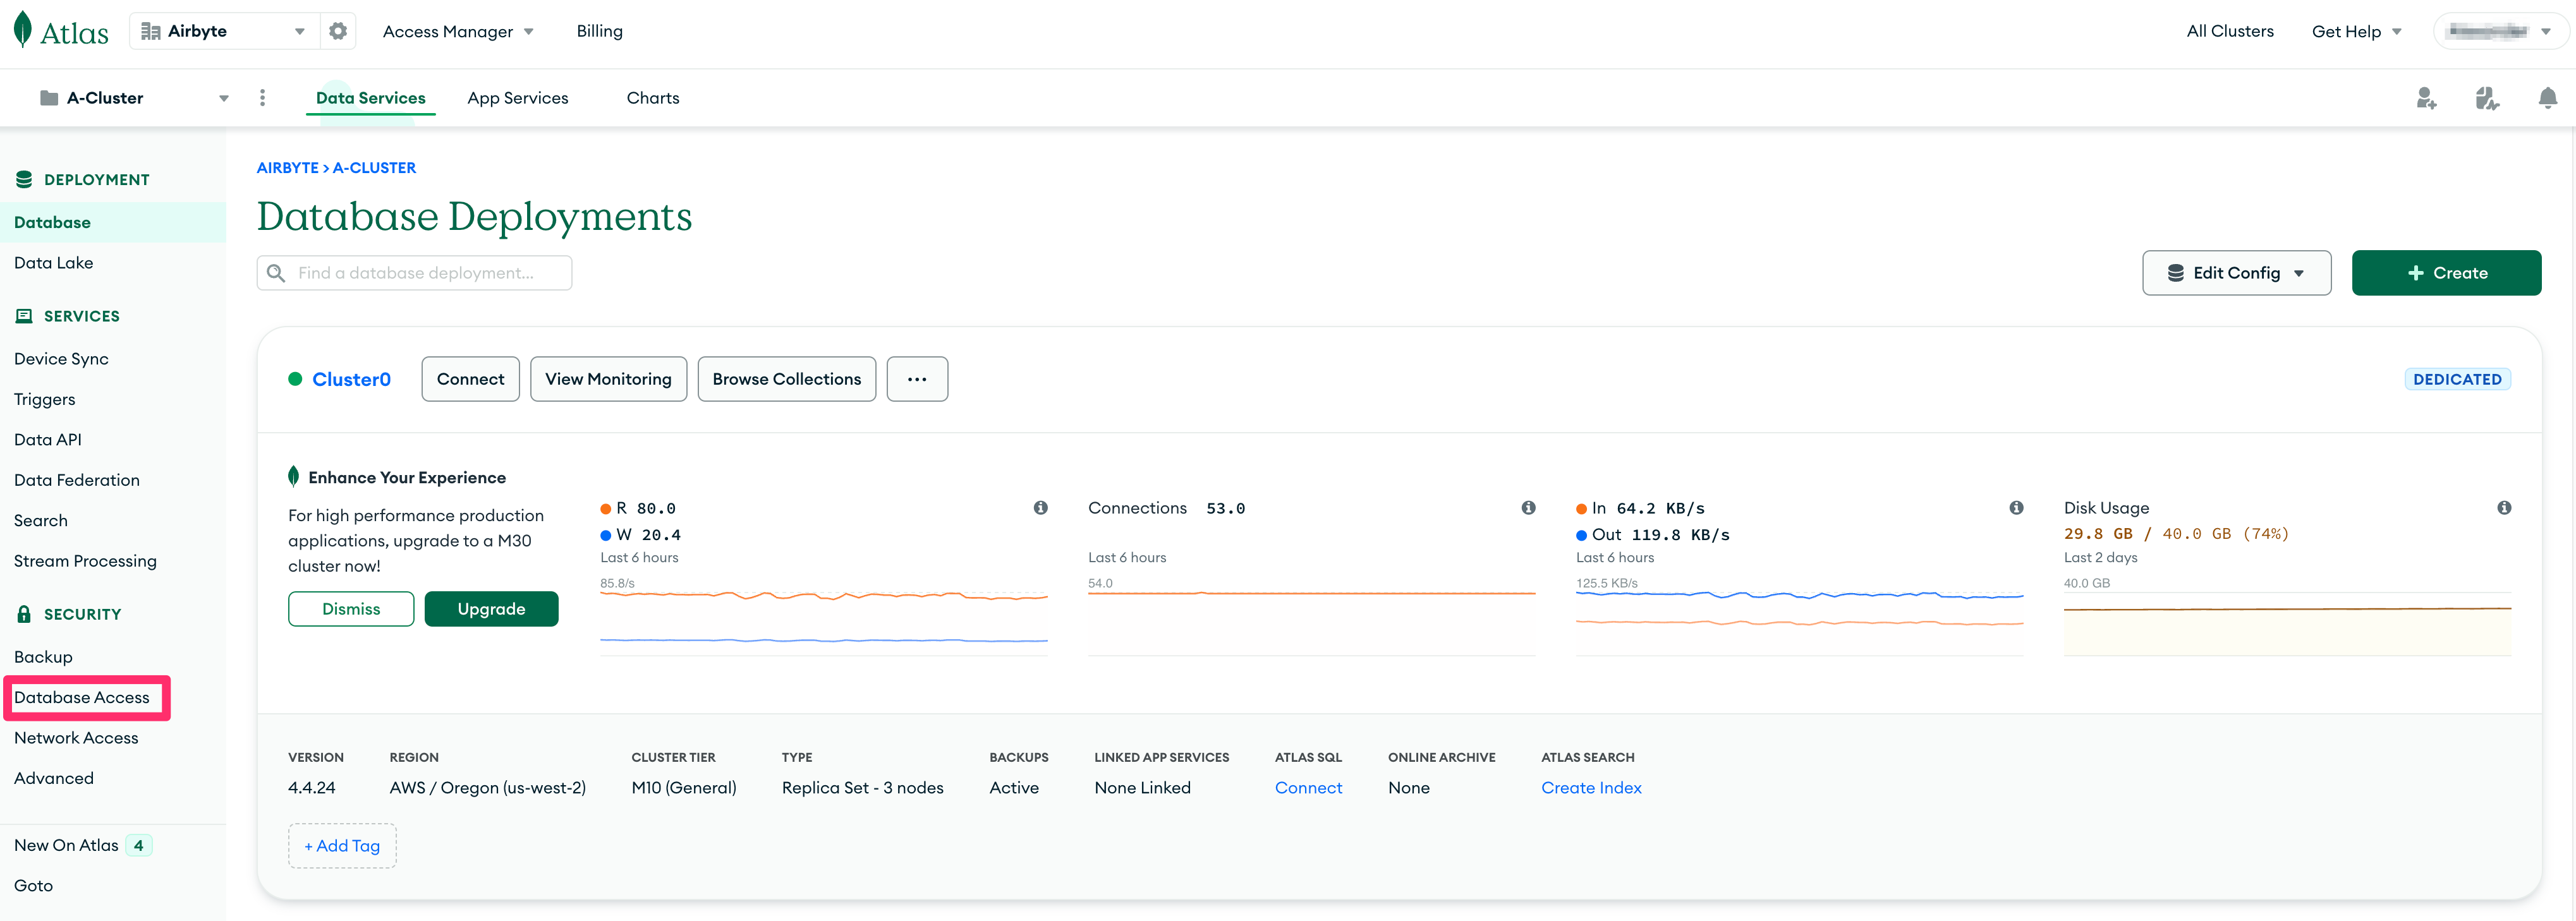
From the dashboard, click on "Database Access" under "Security".
-
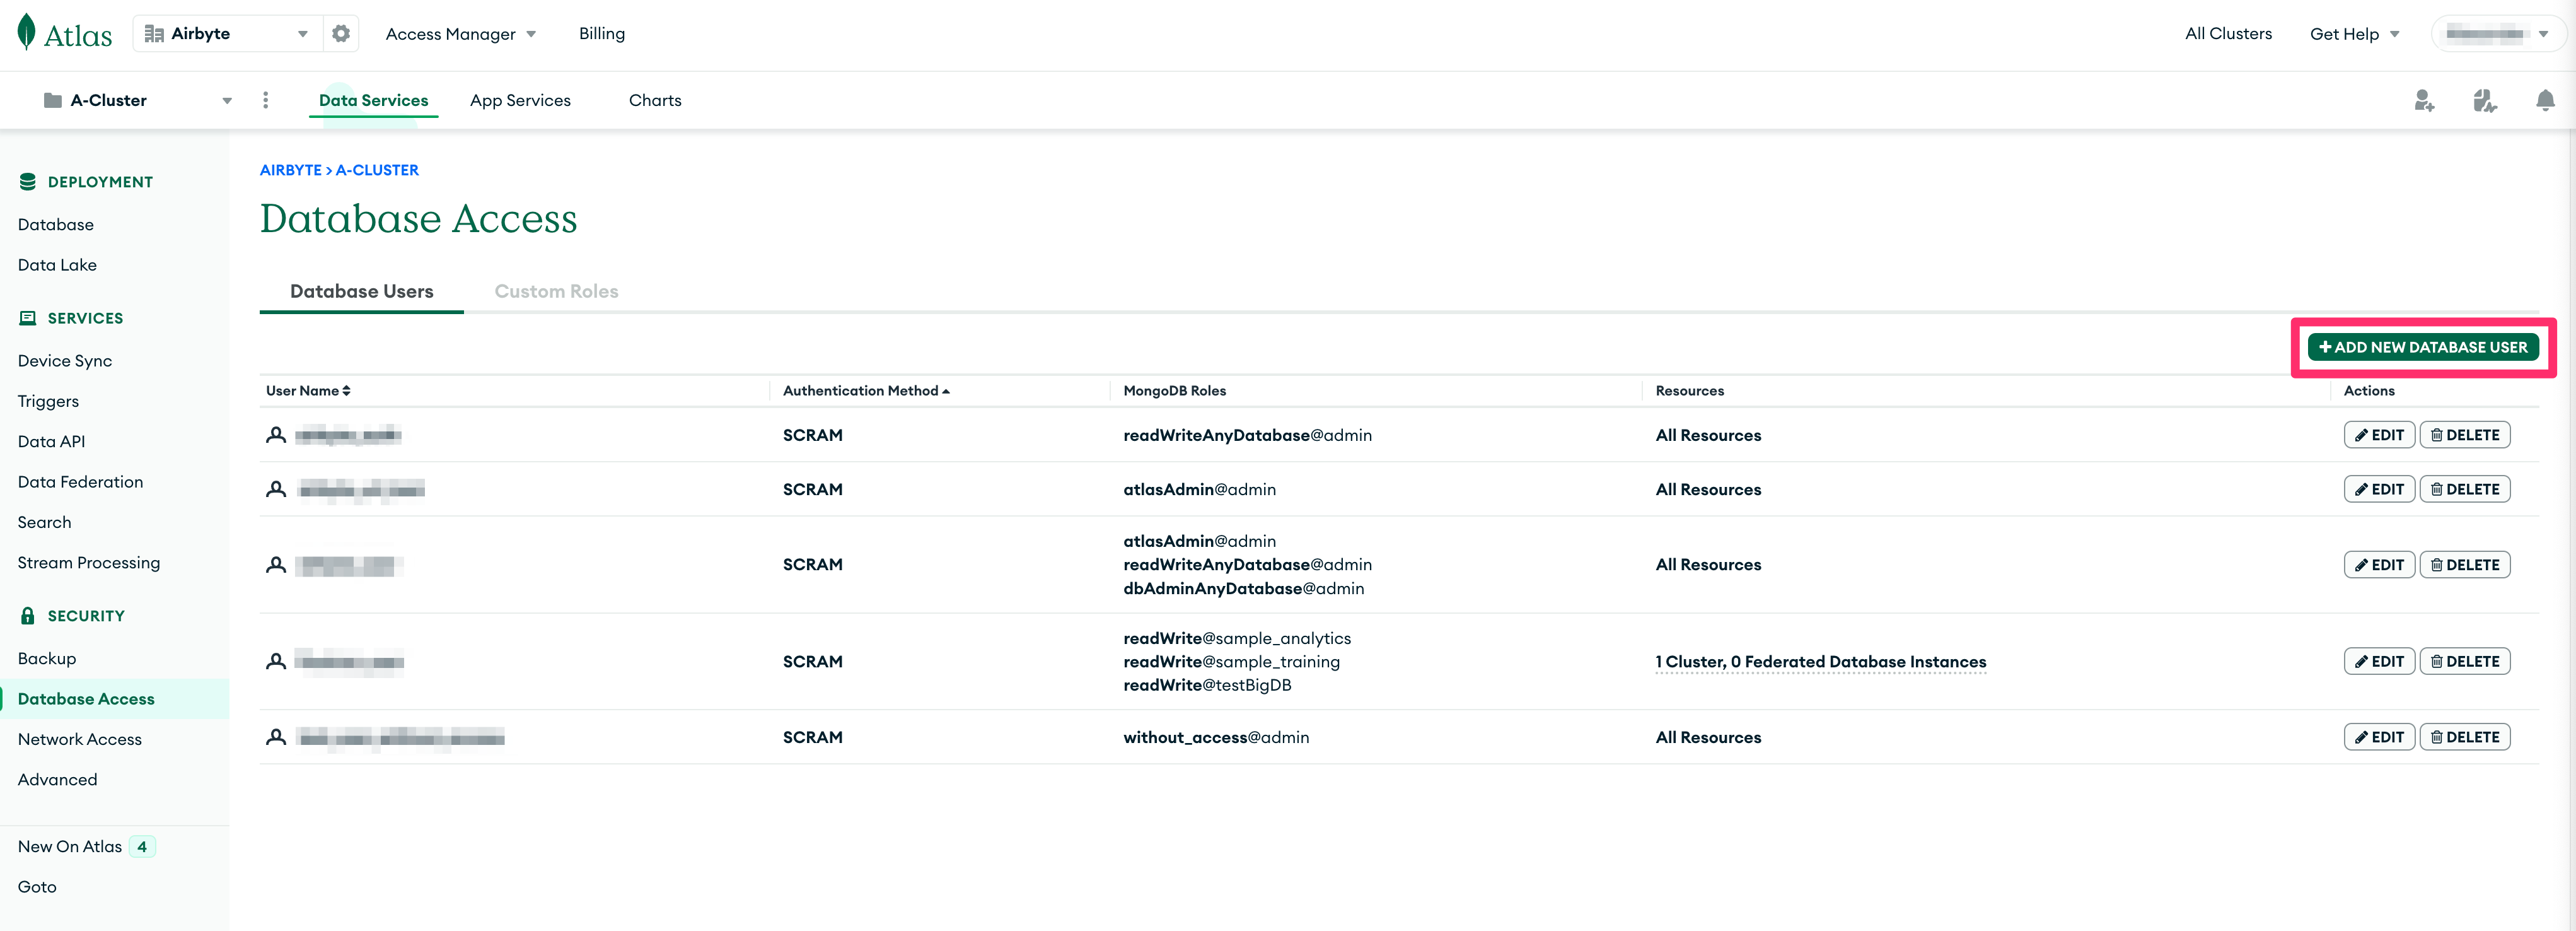
Click on the "+ ADD NEW DATABASE USER" button.
-
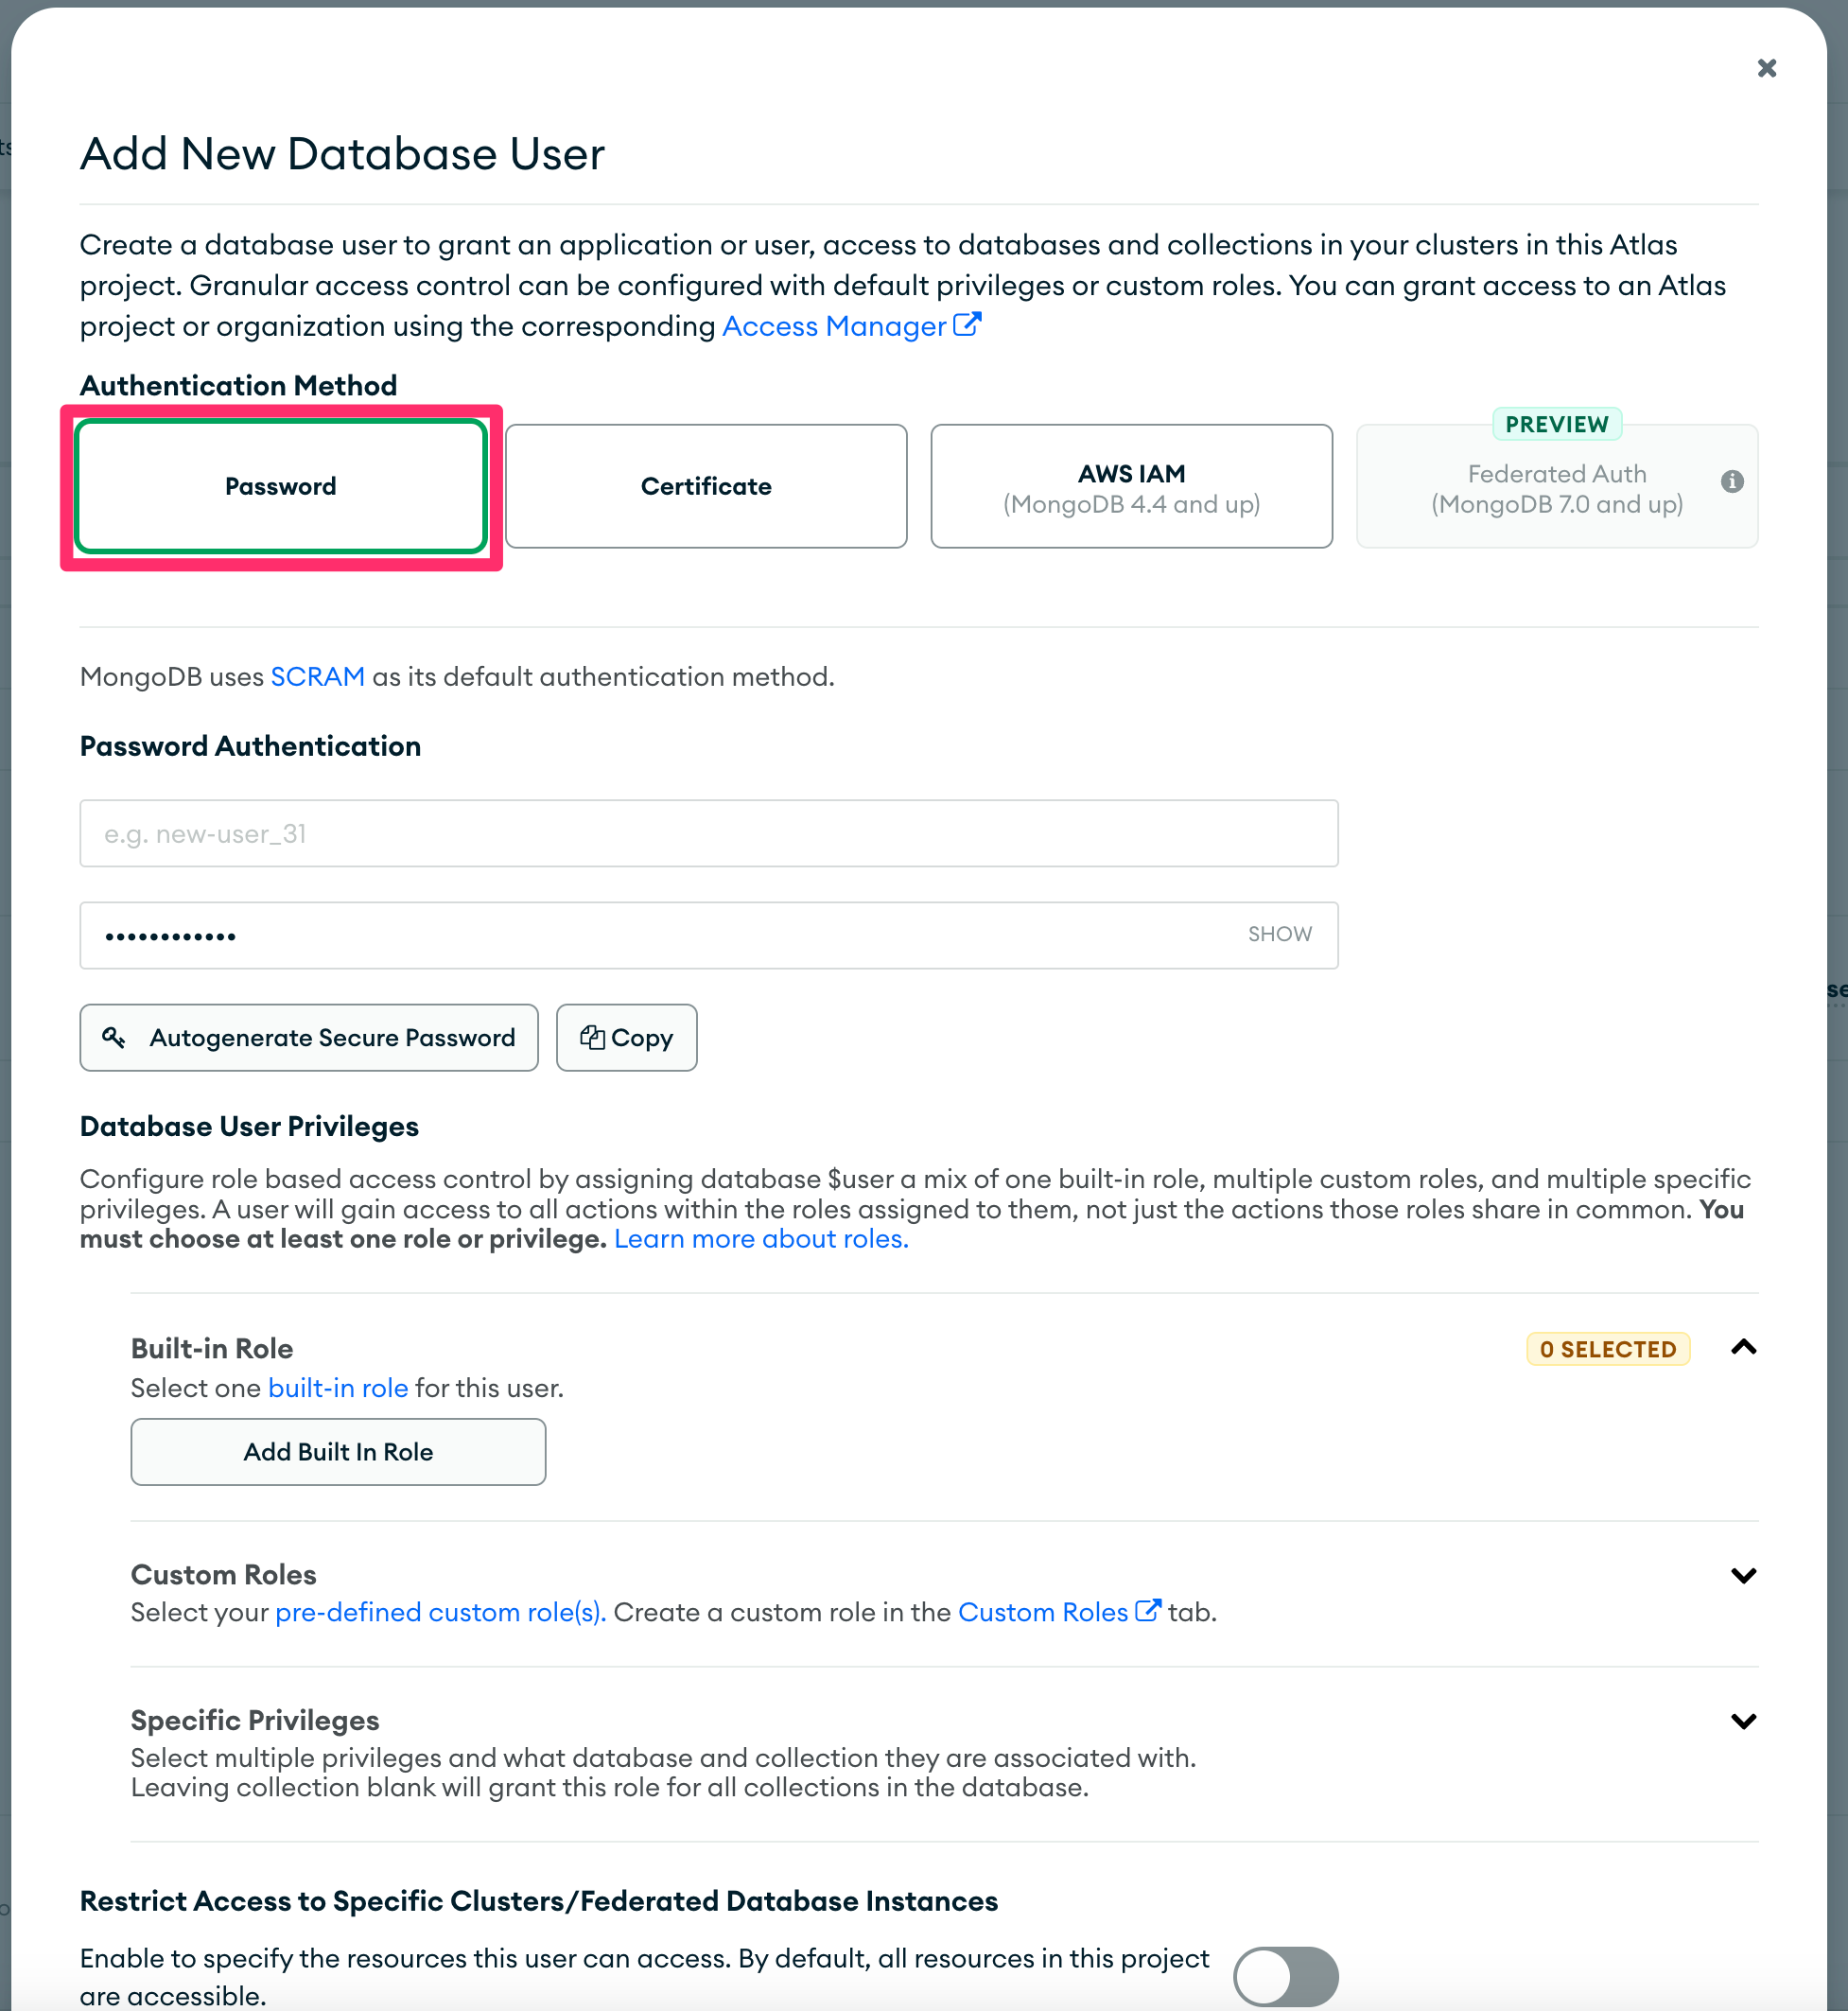
On the "Add new Database User" modal dialog, choose "Password" for the "Authentication Method".
-
In the "Password Authentication" section, set the username to
READ_ONLY_USER(or a name of your choice) in the first text box and set a password in the second text box. You will enter both in the Airbyte source in Step 3.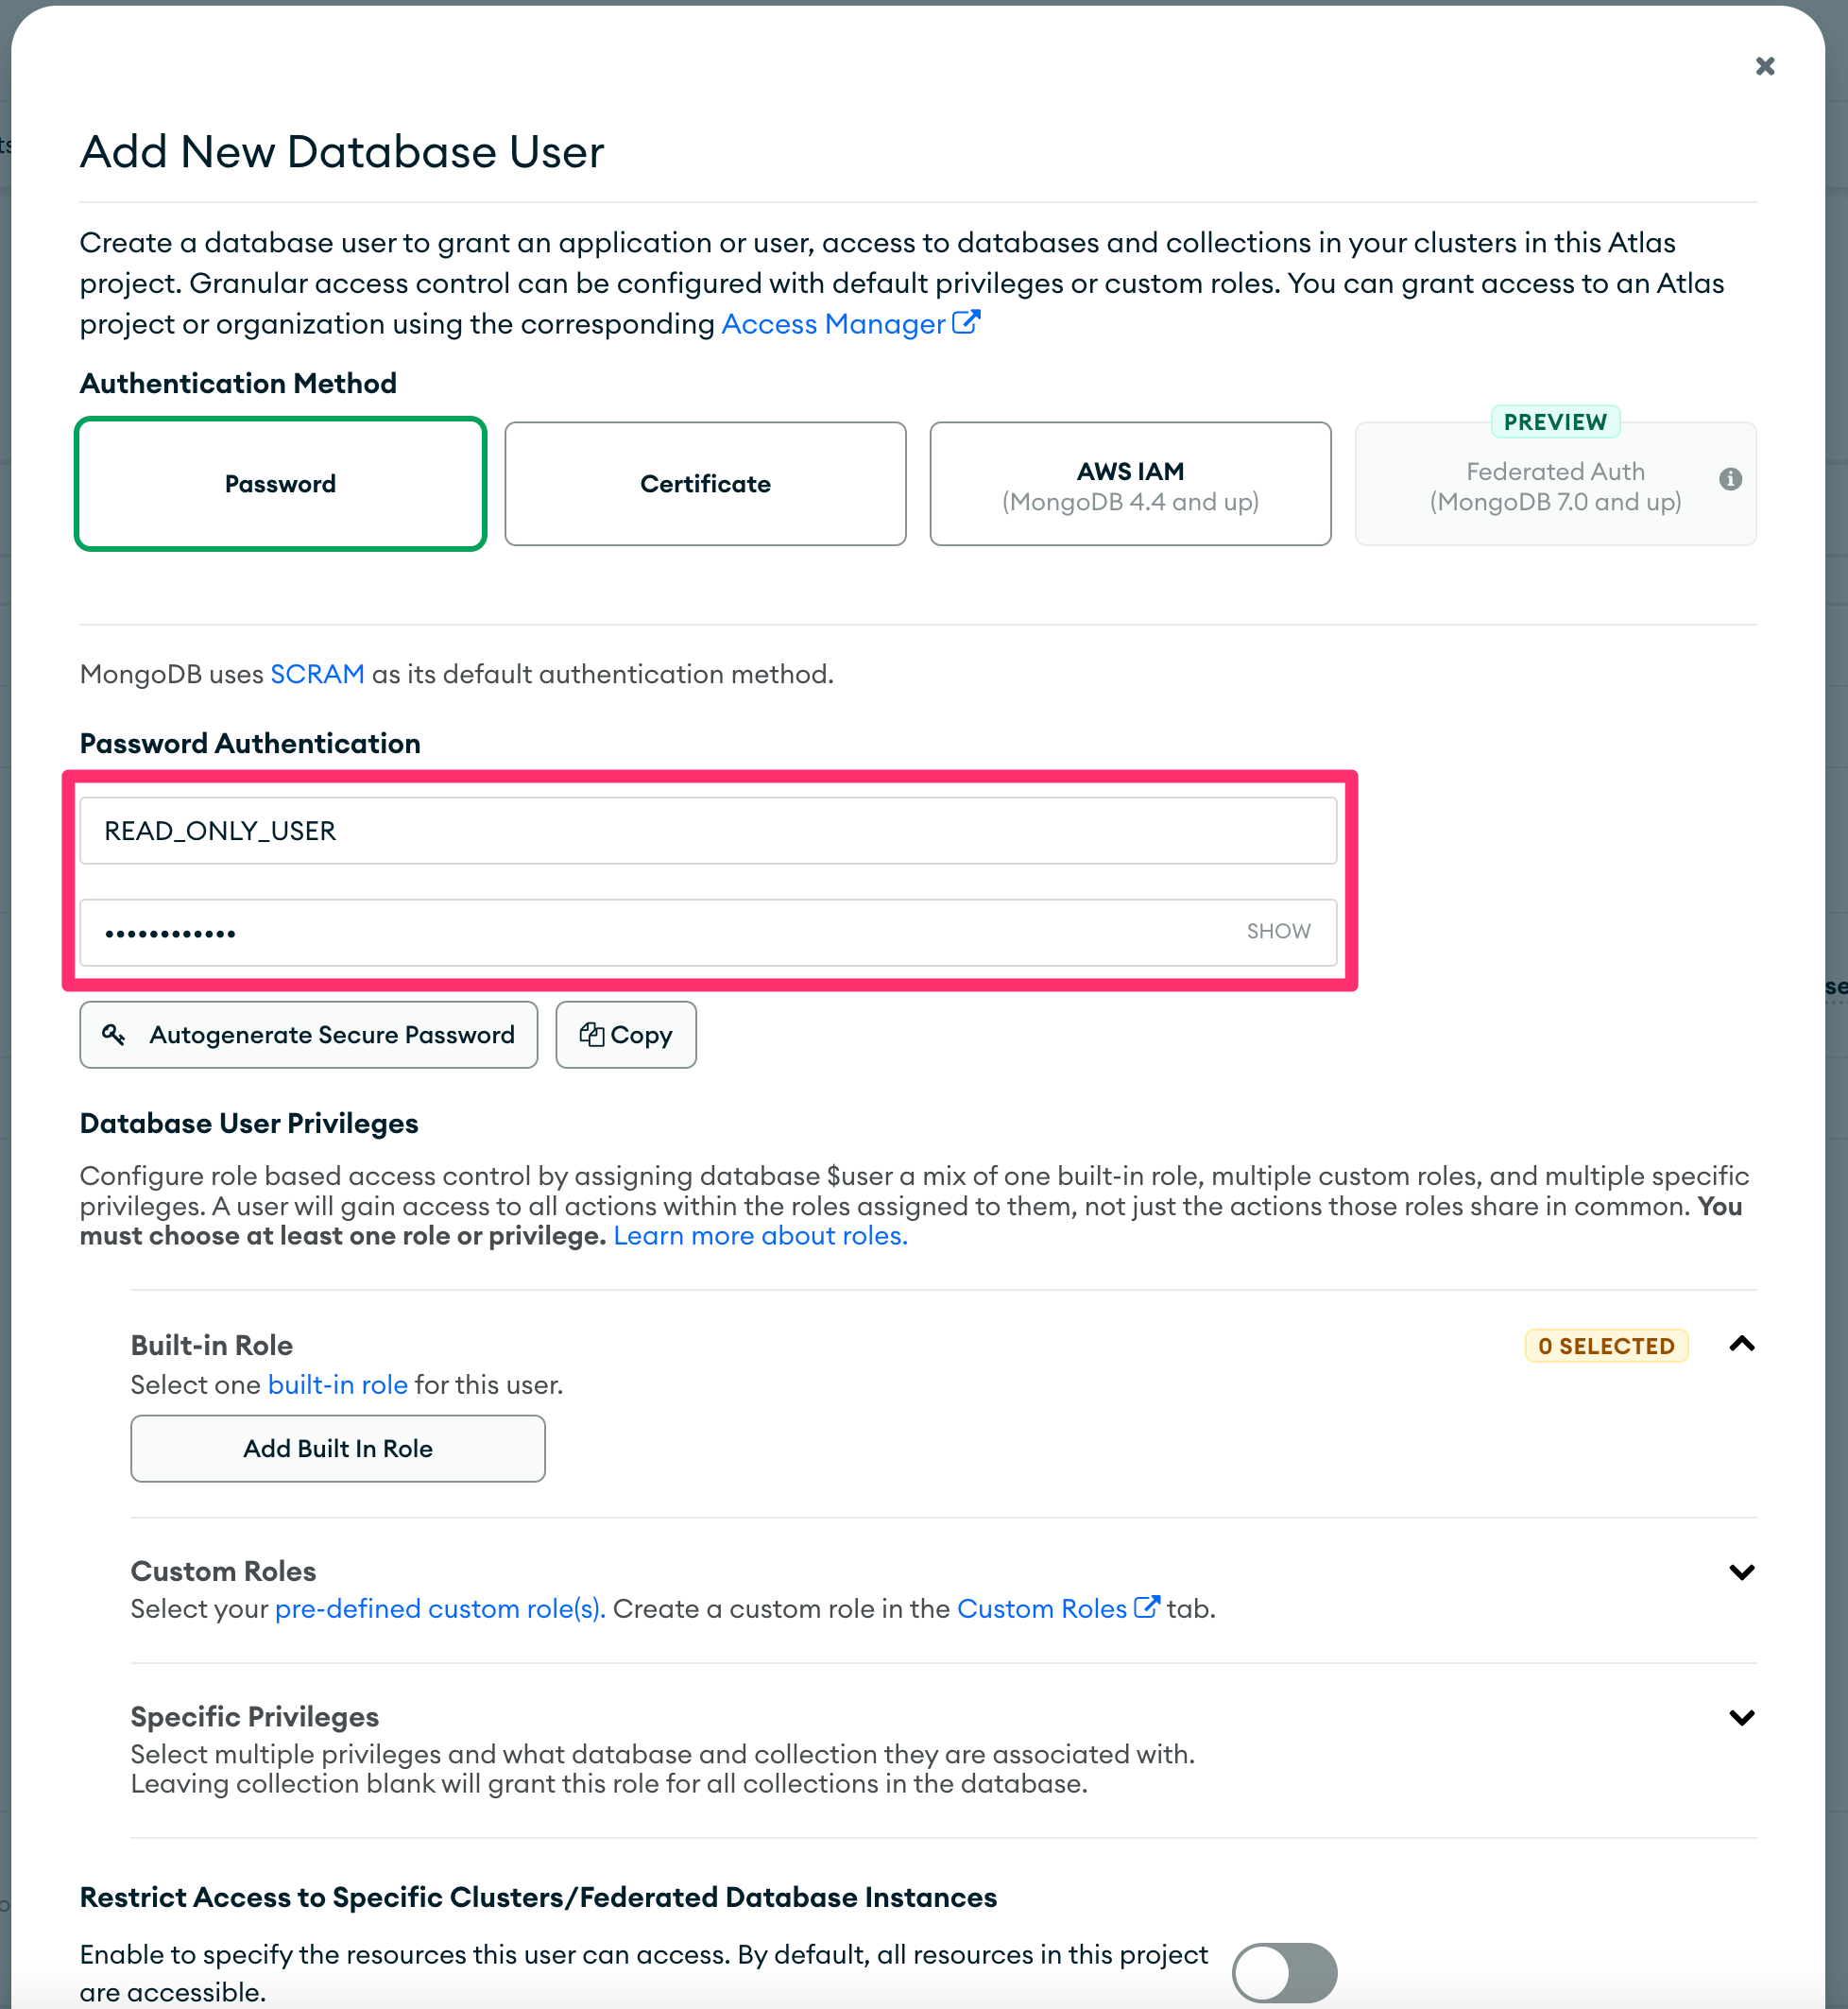
-
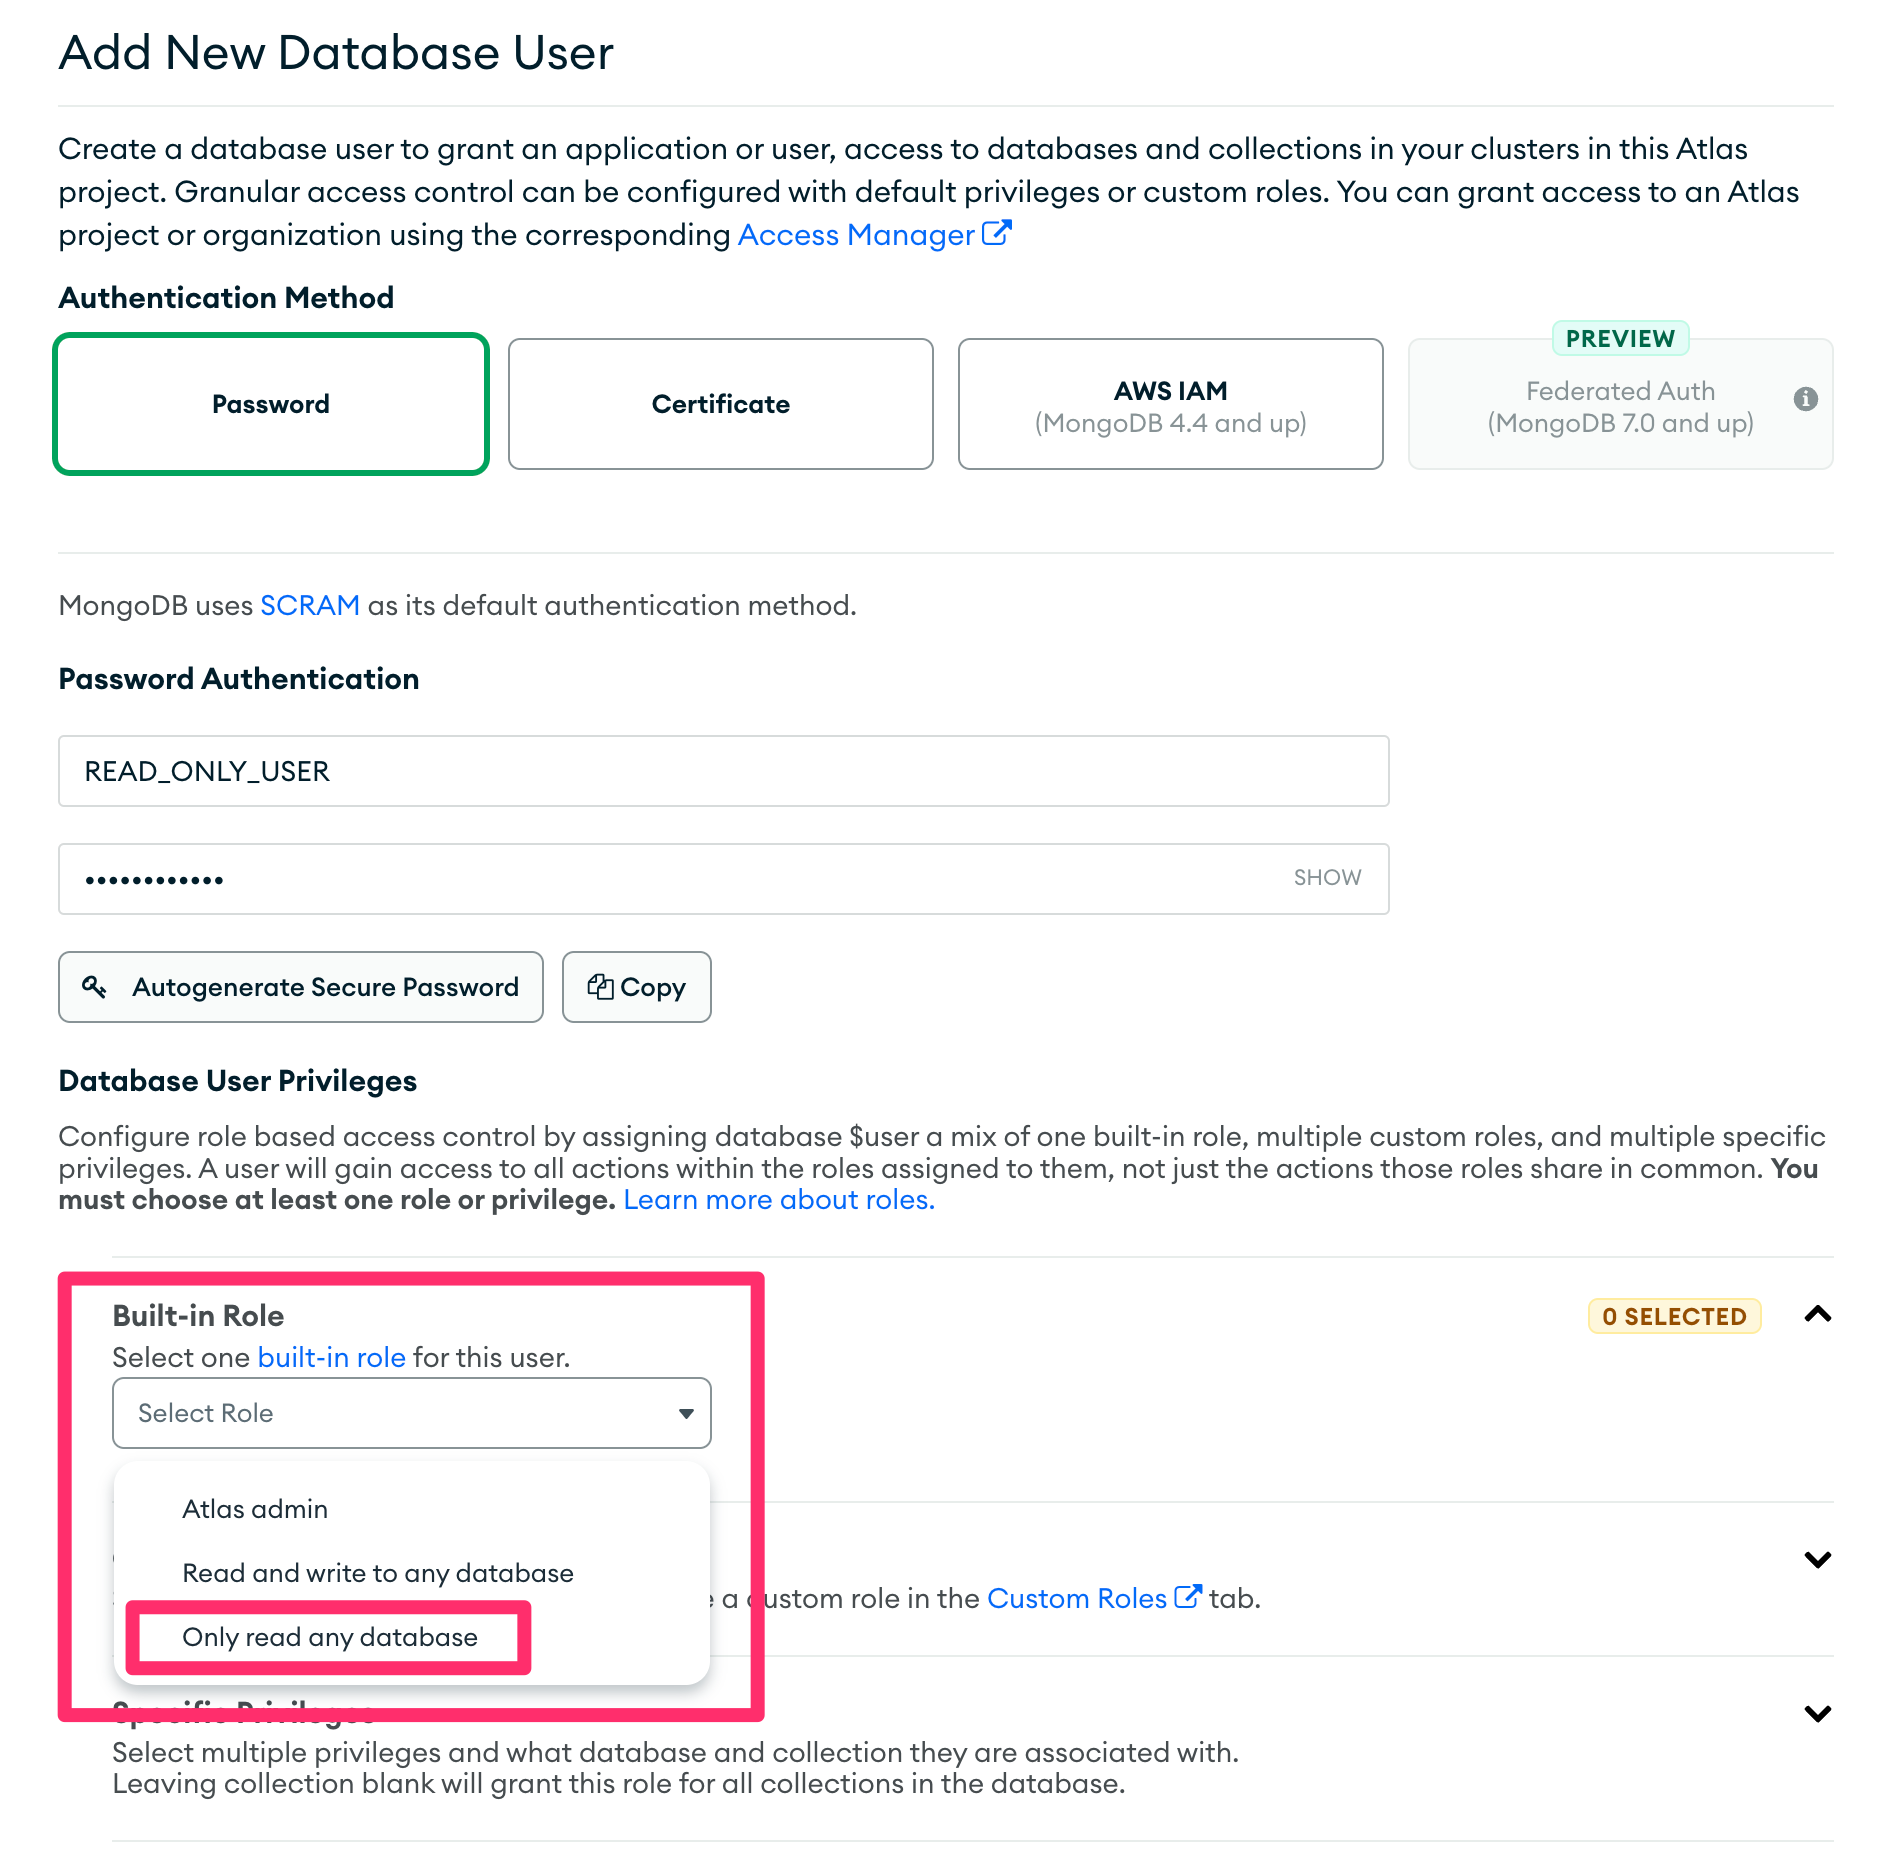
Under "Database User Privileges", grant read access in one of two ways:
-
Under "Built-in Role", click "Select one built-in role for this user" and choose "Only read any database".
-
Or, under "Specific Privileges", click "Add Specific Privilege" and add
readAnyDatabase.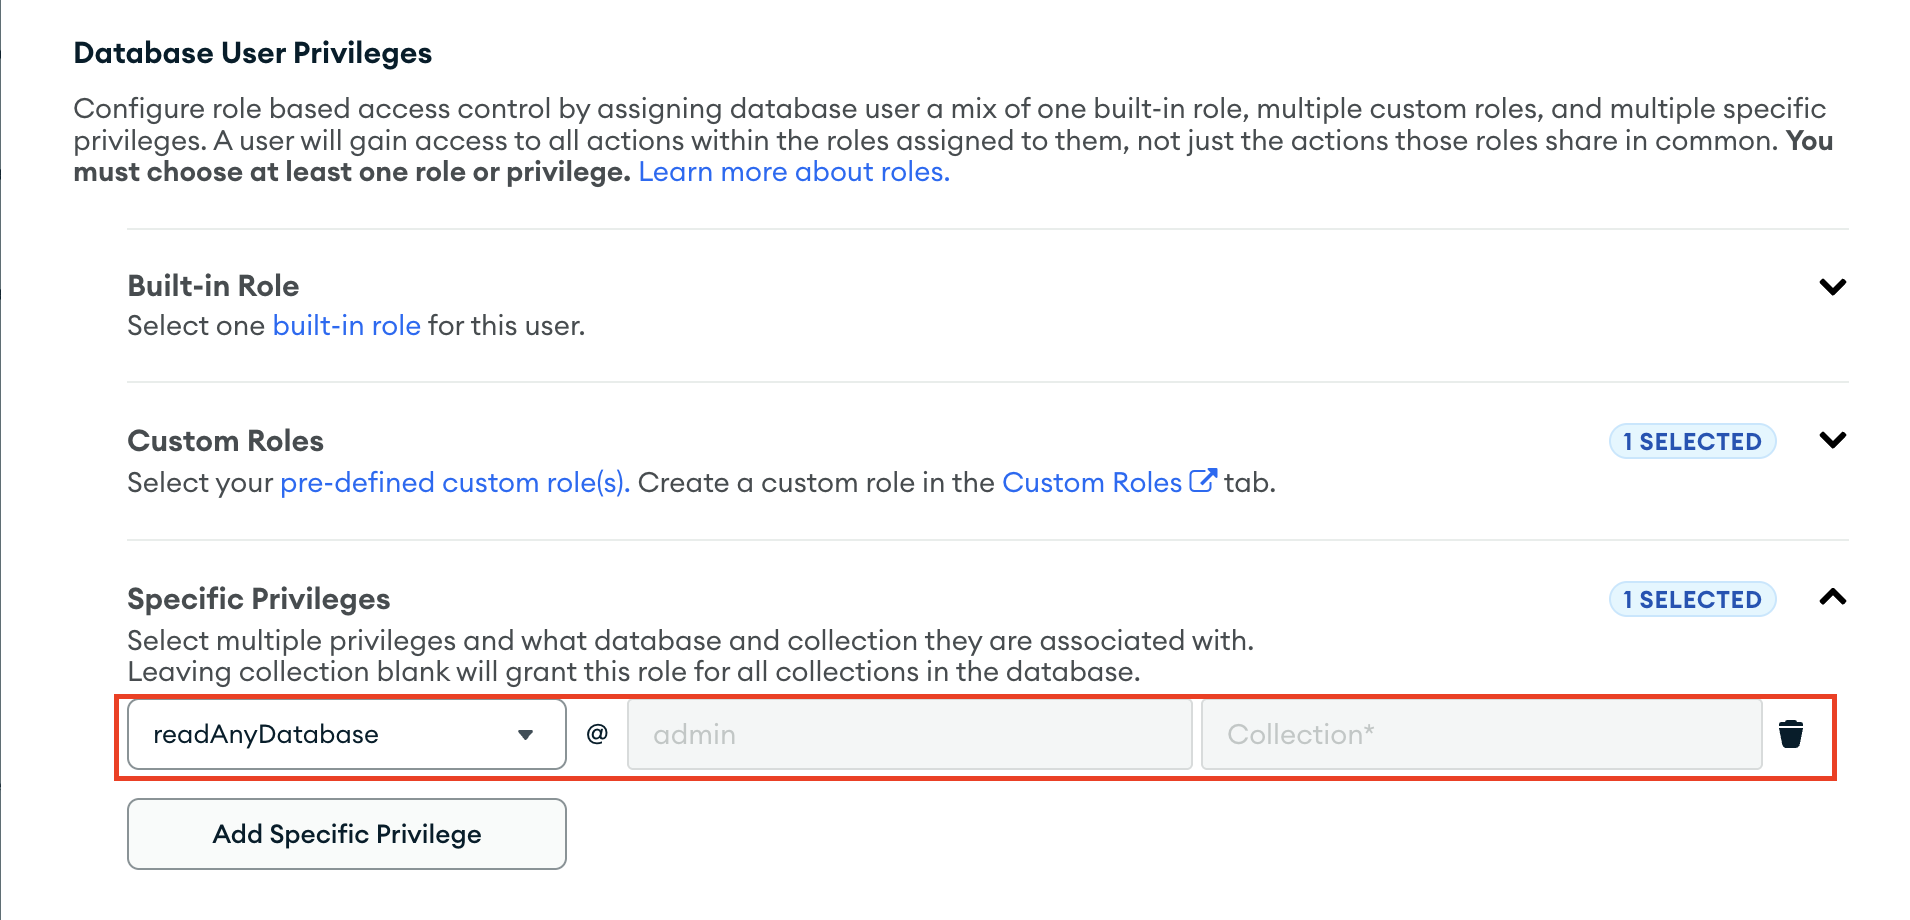
-
Both grant readAnyDatabase, which is required when you configure more than one database. If you sync a single database and prefer narrower privileges, use a custom role with the read role on that database instead.
-
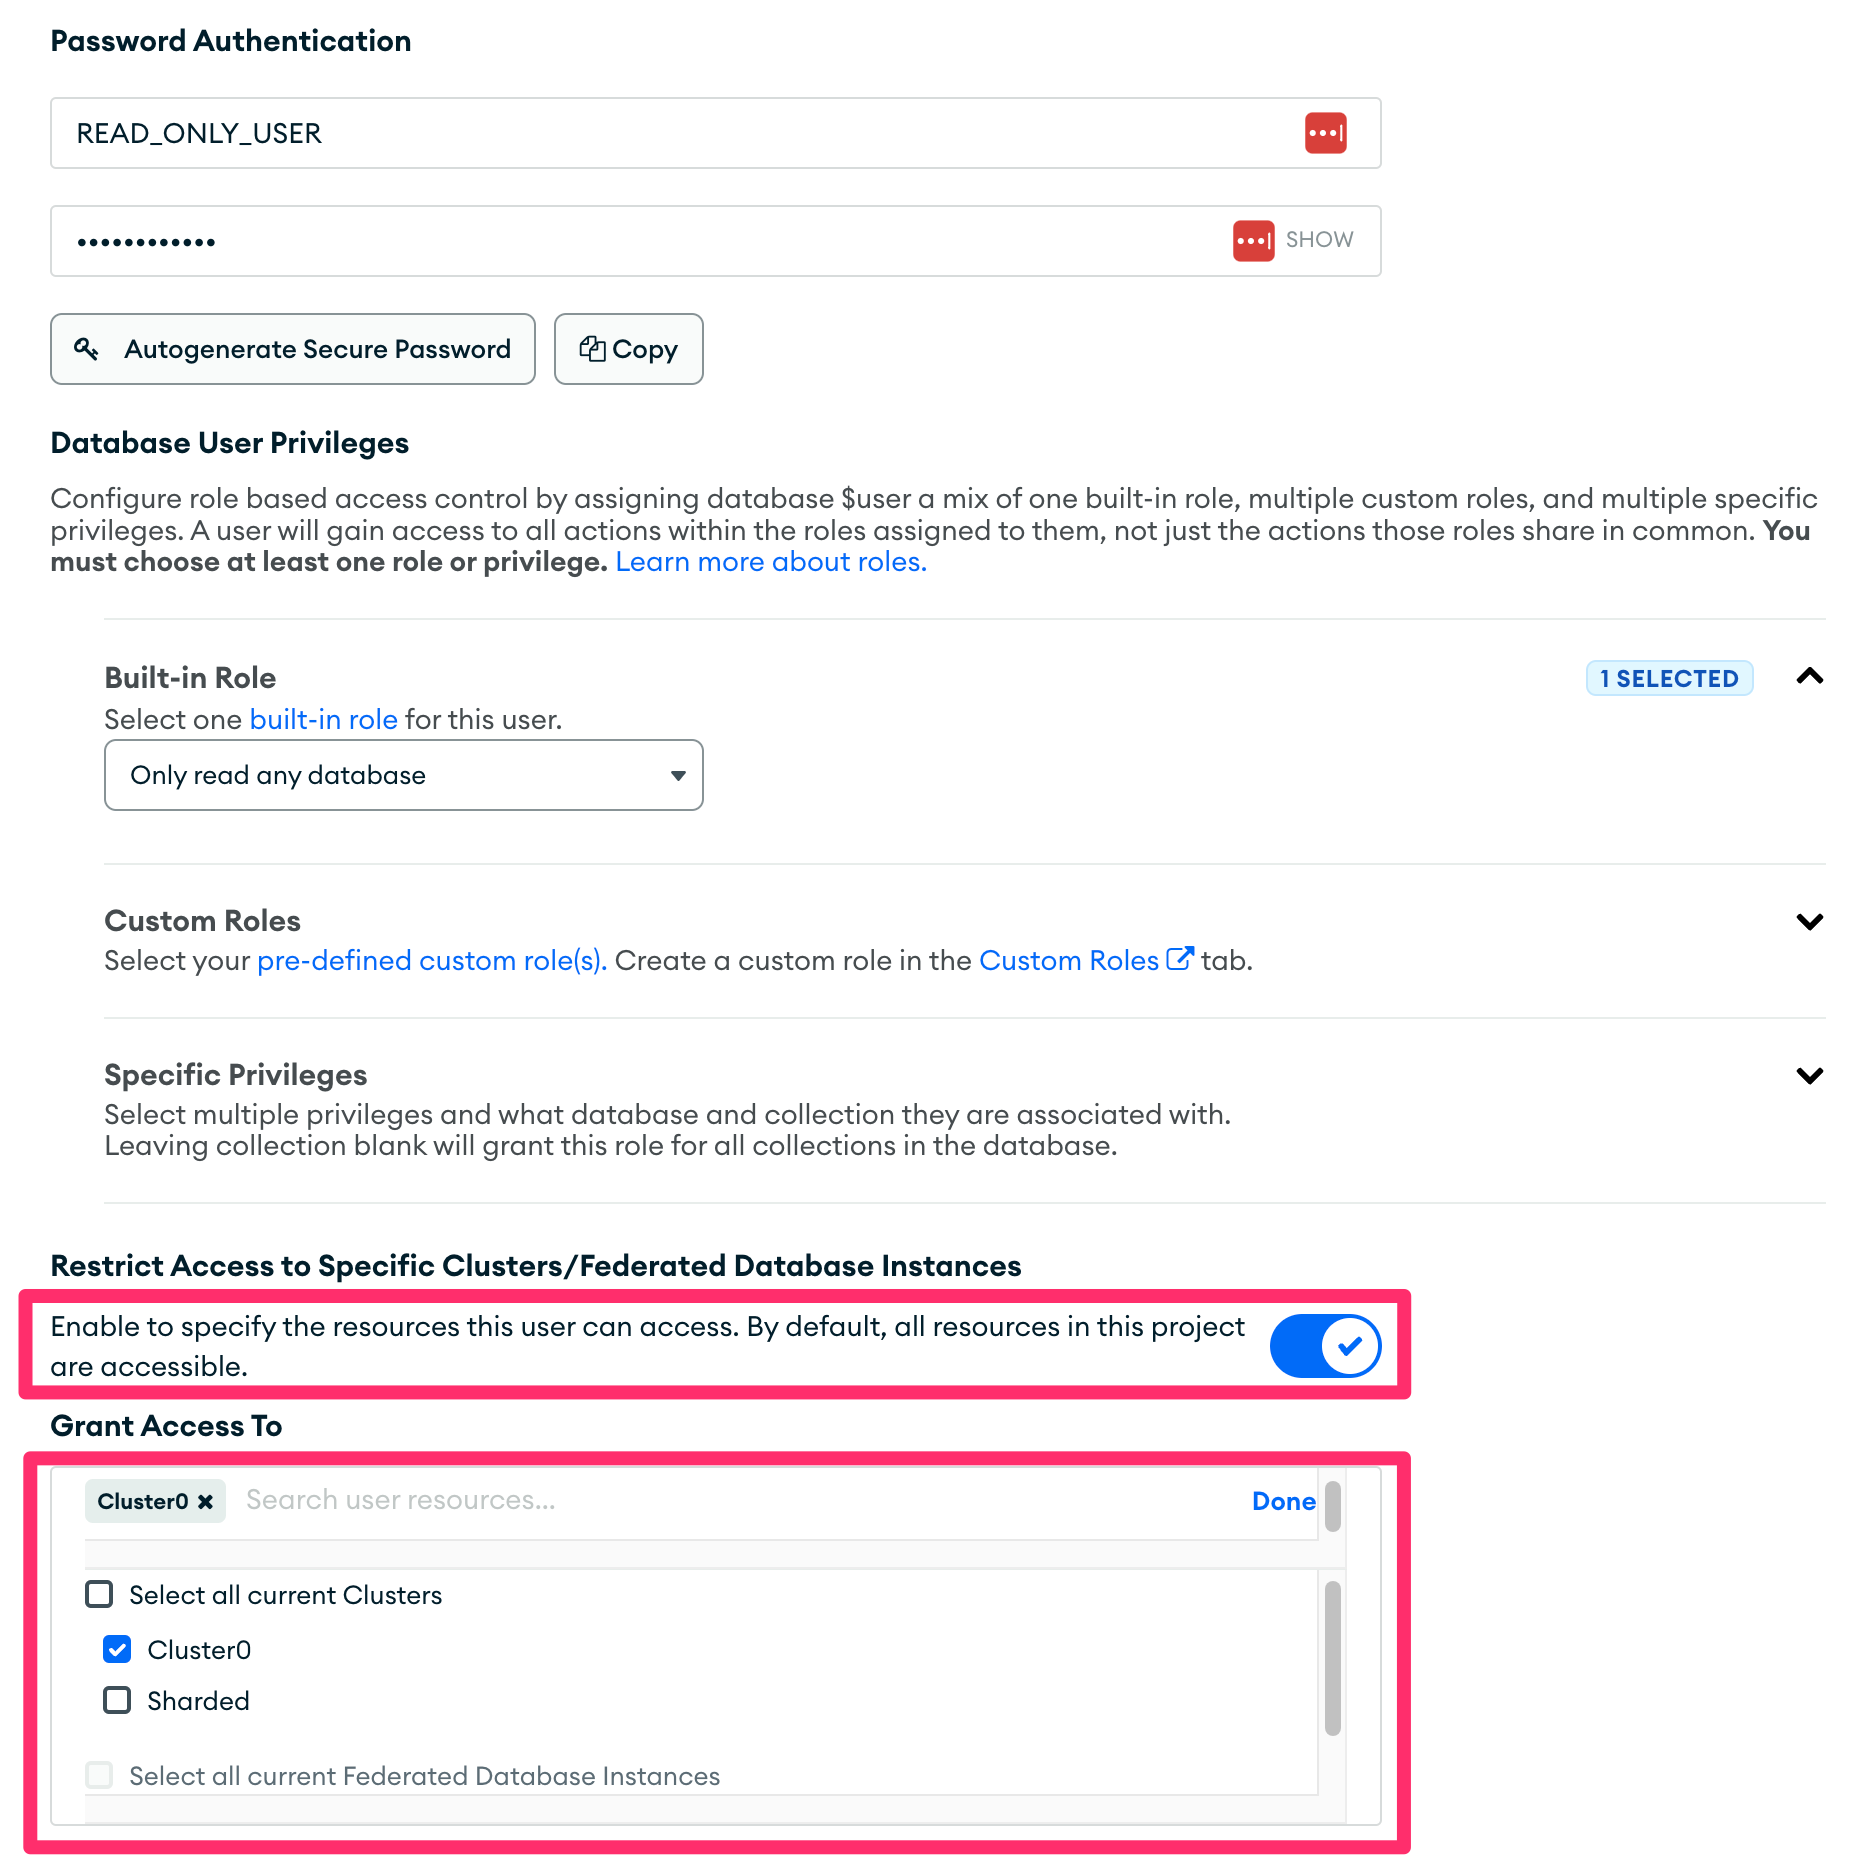
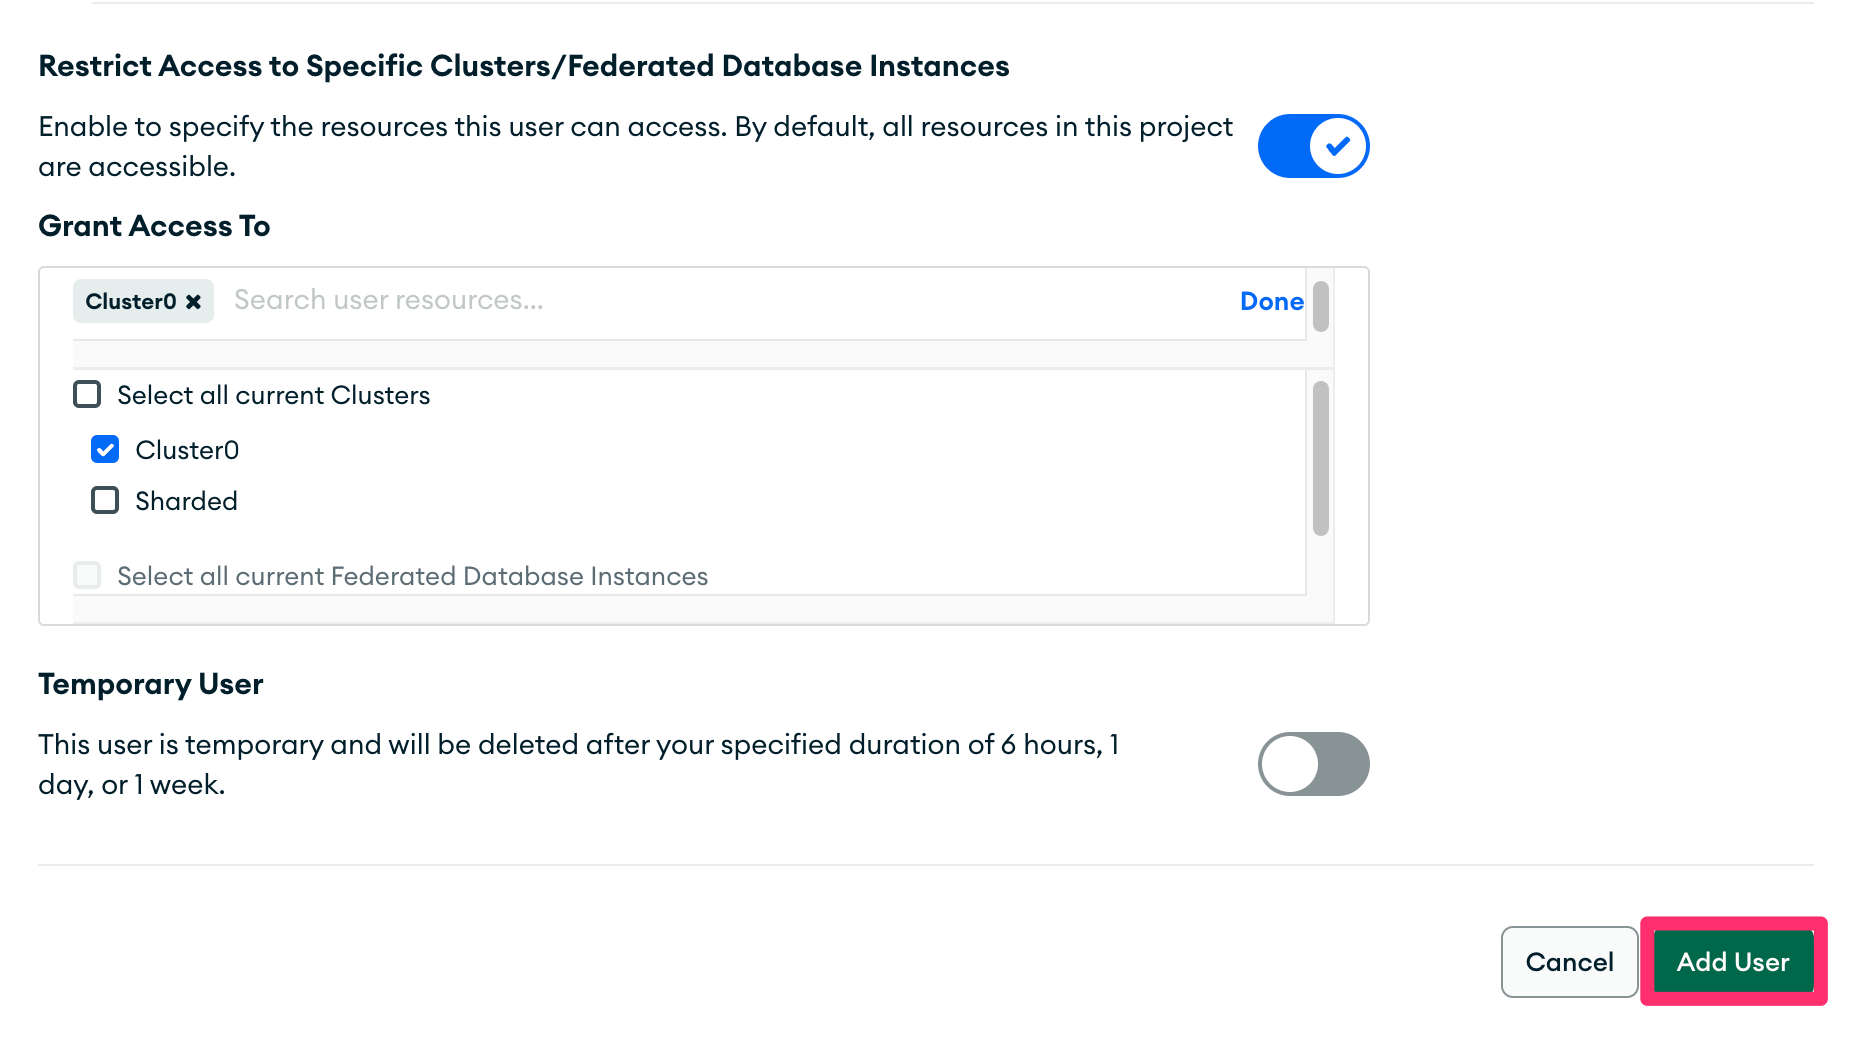
Enable "Restrict Access to Specific Clusters/Federated Database instances" and select only the cluster you want to replicate.
-
Click on "Add User" at the bottom to save the user.
Self-hosted
These instructions use the MongoDB shell (mongosh). To install it, follow these instructions.
-
From a terminal window, connect to the cluster as a user who can create users (for example one with the
userAdminAnyDatabaserole):> mongosh "<connection string to cluster>" --username <user with admin permissions> -
Switch to the
admindatabase:test> use adminswitched to db admin -
Create the
READ_ONLY_USERuser (or a name of your choice). To sync one database, grant thereadrole on it:admin> db.createUser({user: "READ_ONLY_USER", pwd: "READ_ONLY_PASSWORD", roles: [{role: "read", db: "TARGET_DATABASE"}]})To sync several databases, grant
readAnyDatabaseinstead:admin> db.createUser({user: "READ_ONLY_USER", pwd: "READ_ONLY_PASSWORD", roles: [{role: "readAnyDatabase", db: "admin"}]})
Replace READ_ONLY_PASSWORD with a password of your choice and TARGET_DATABASE with the name of the database to be replicated. Create the user in the admin database: the connector authenticates against admin.
-
Make sure every member of the replica set (or every
mongos) requires authentication and accepts connections from the network Airbyte runs on. In each member's configuration file (/etc/mongod.confon most Linux distributions), check these keys and restart the process after changing them:net:bindIp: localhost,<the interface Airbyte reaches this member on>security:authorization: enabled
net.bindIp lists the interfaces the member listens on; 0.0.0.0 accepts connections from any interface, so if you use it, restrict access with a firewall or the IP allow list of Step 4. security.authorization: enabled makes the member reject unauthenticated clients. On a replica set, members also need to authenticate with each other (a keyfile or x.509 certificates); see Internal/Membership Authentication.
Step 2: Find the MongoDB cluster connection string
MongoDB Atlas
Atlas is MongoDB's cloud-hosted offering. To find the connection string of an Atlas-hosted cluster:
-
Log in to the MongoDB Atlas dashboard.
-
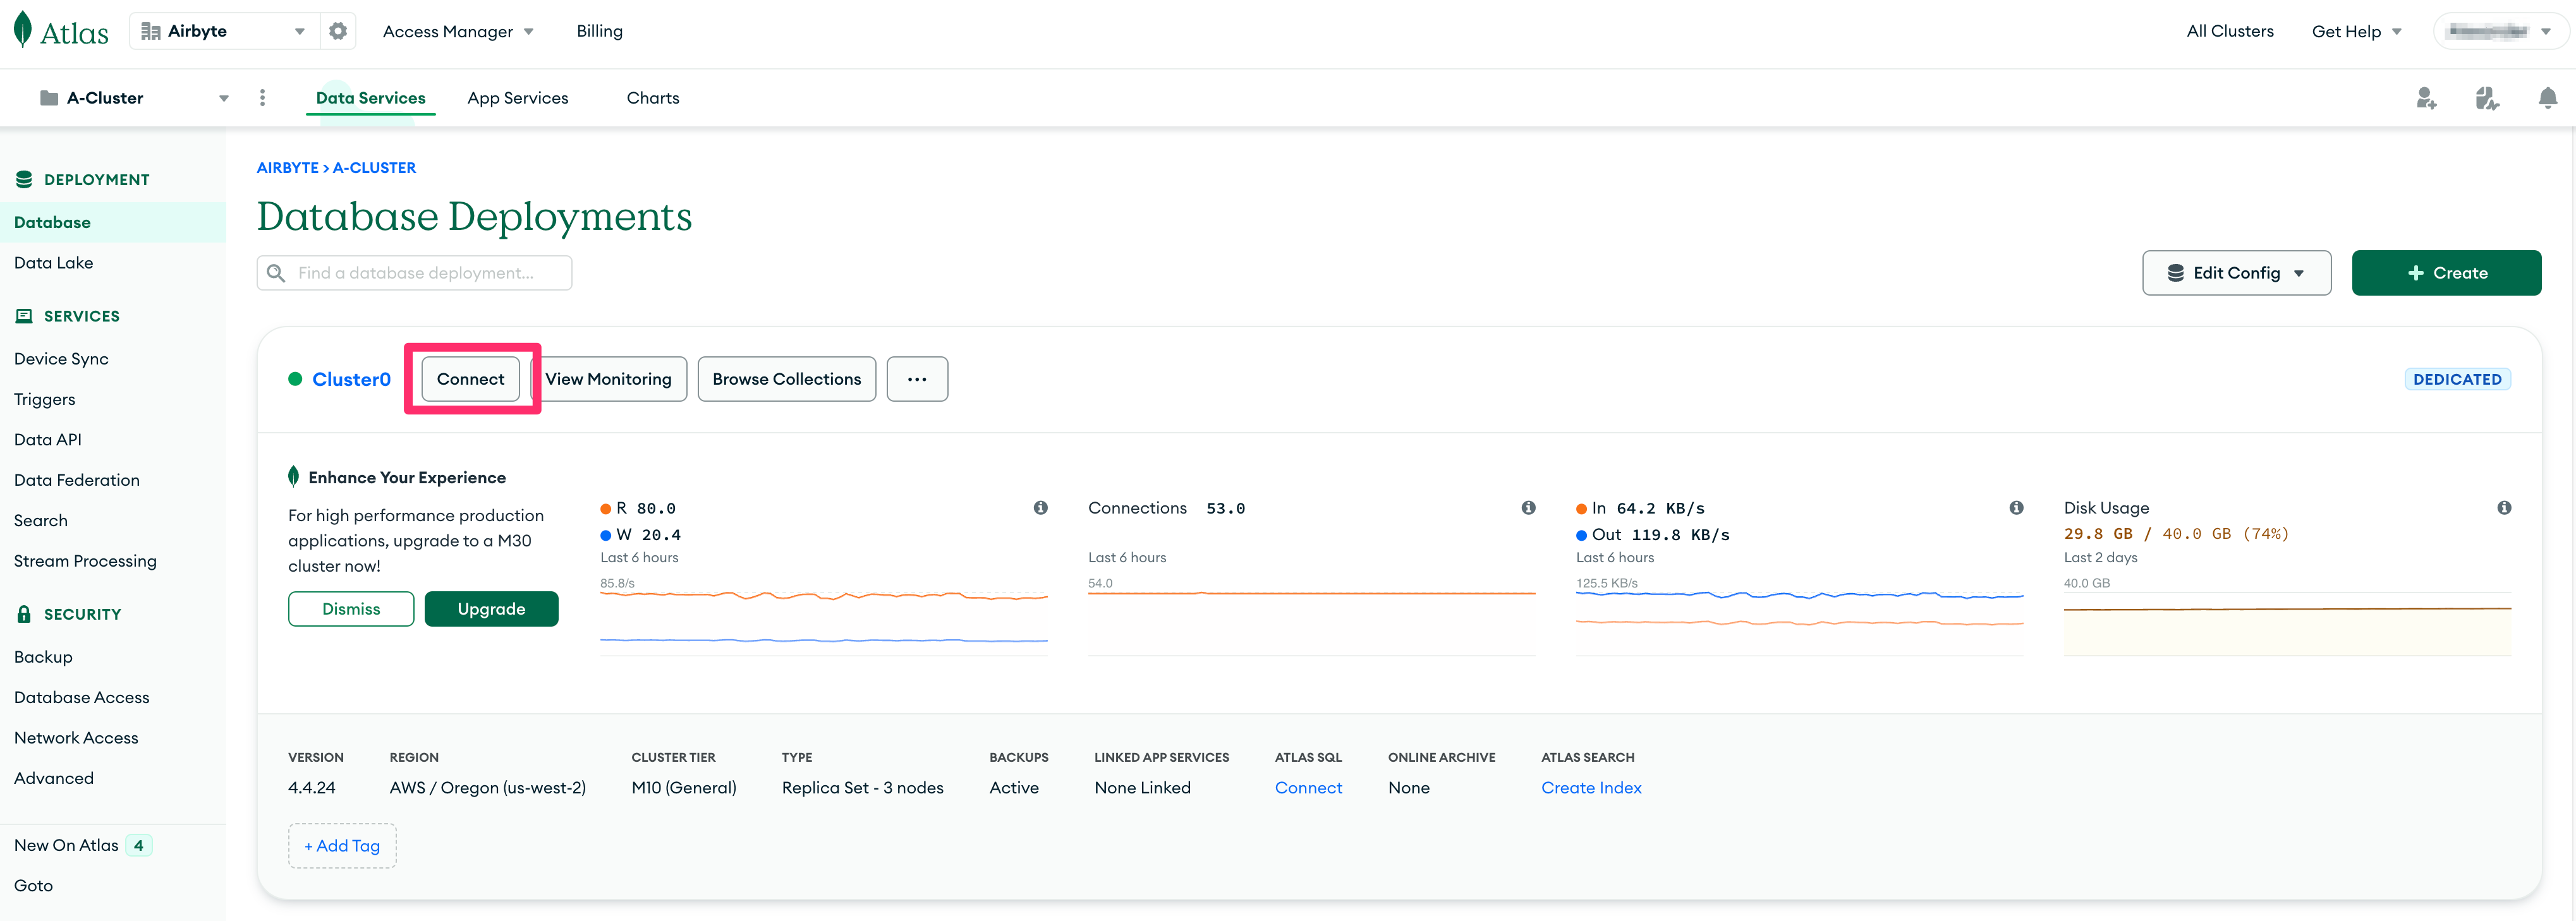
From the dashboard, click on the "Connect" button of the source cluster.
-
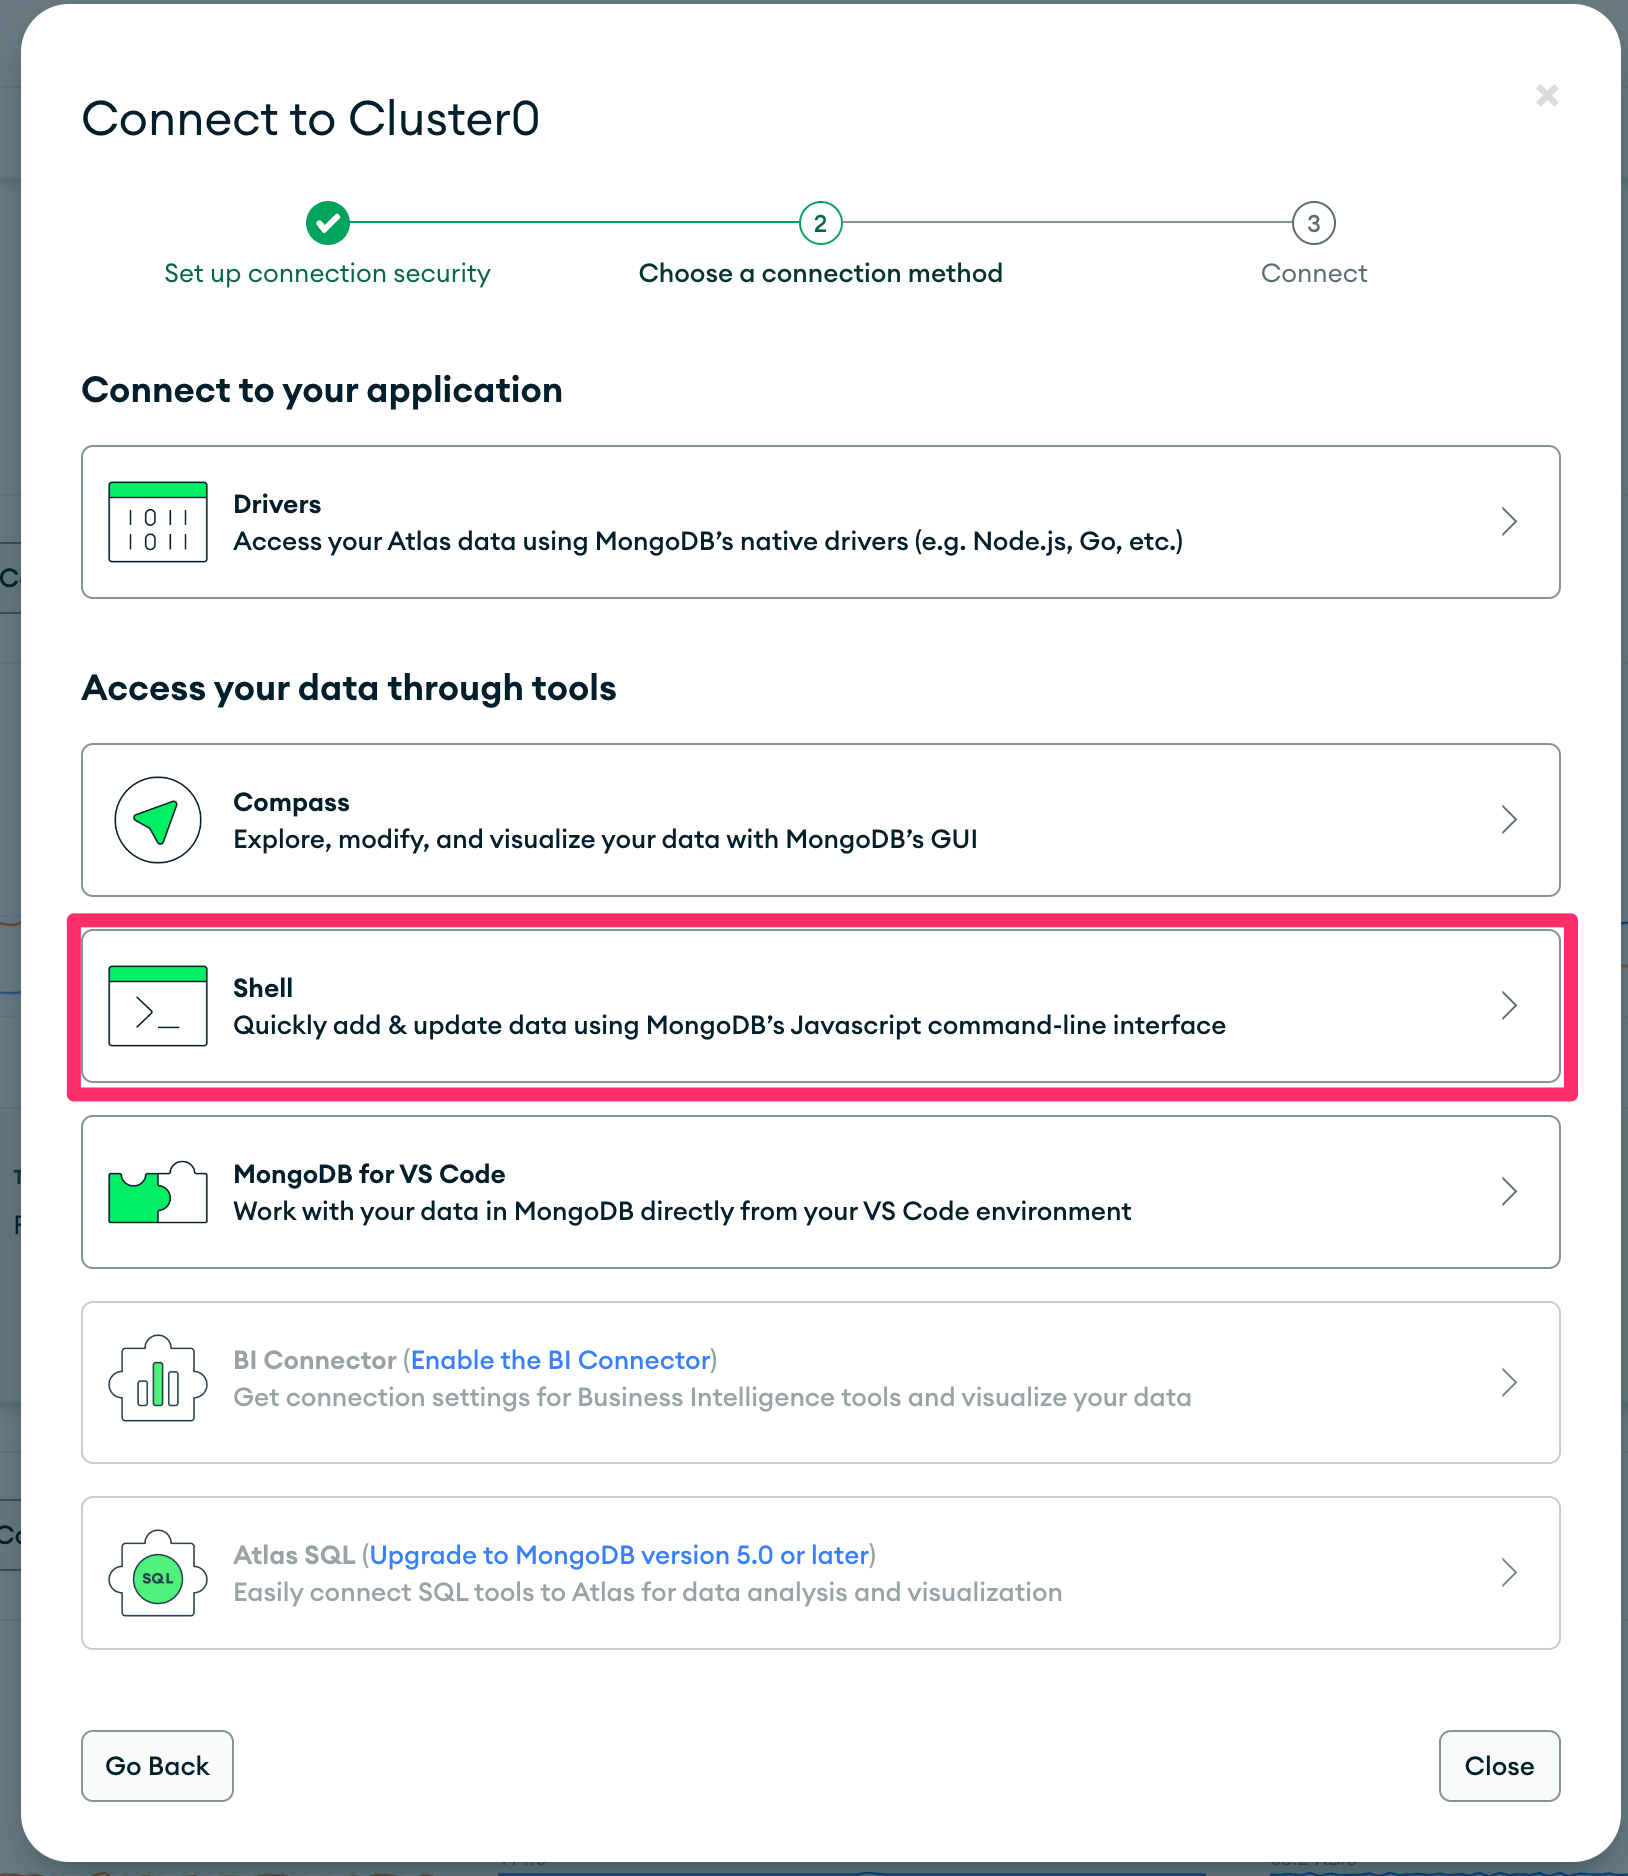
On the "Connect to <cluster name>" modal dialog, select "Shell" under the "Access your data through tools" section.
-
Copy the connection string from the entry labeled "2. Run your connection string in your command line" on the modal dialog.
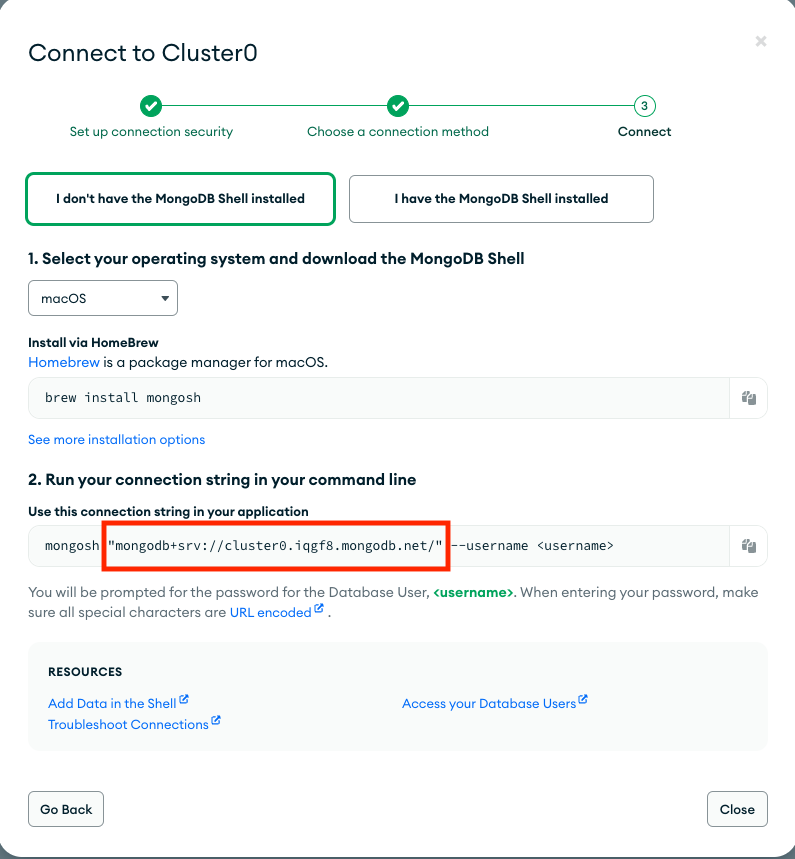
The string looks like mongodb+srv://cluster0.abcde.mongodb.net/. You can paste it as Atlas shows it: surrounding quotation marks and the <username>:<password>@ placeholder are removed by the connector. Enter the credentials in the Username and Password fields of the source instead, where the password is stored as a secret. Connections to Atlas always use TLS.
Self-hosted cluster
Refer to the MongoDB connection string documentation for instructions on finding a self-hosted deployment's connection string. List every member of the replica set, or the mongos routers of a sharded cluster, so the connector can fail over when a member is down — for example mongodb://host1:27017,host2:27017,host3:27017/?replicaSet=rs0. DNS seed lists (mongodb+srv://) work too.
Connection string options are honored. In particular:
- Add
tls=trueto connect over TLS. See Configure mongod and mongos for TLS/SSL. - Set
readPreferenceto choose which members serve the reads. When the connection string does not set one, the connector usessecondaryPreferred, so the initial snapshot and the change stream are read from a secondary when one is available and the primary is left to your application. - Set
compressorsto choose how traffic from the cluster is compressed. When the connection string does not set it, the connector asks forsnappy, thenzlib, and uses the first one the cluster supports. An emptycompressors=turns compression off. - Credentials may be embedded (
mongodb://user:password@host…), but the Username and Password fields are preferred: the connection string is stored in clear, the password field as a secret. When both are set, the fields win.
Step 3: Configure the Airbyte MongoDB source
In Airbyte, go to Sources, click + New source and choose MongoDB. Then fill in:
- Cluster Type: MongoDB Atlas or self-hosted.
- Connection String: the string from Step 2.
- Database Names: the databases that contain the collections to sync. Add one name per entry; several databases need the
readAnyDatabaseprivilege from Step 1. - Username and Password: the user from Step 1. Required for Atlas; on a self-hosted cluster, leave them empty only if the cluster does not require authentication.
- Schema Enforced: leave it on unless your documents do not share a structure; see Schema Enforcement.
Leave the advanced settings at their defaults unless you have a reason to change them; they are described under Configuration Parameters.
Click Set up source. Airbyte tests the connection before saving: it checks that the cluster can be reached with the credentials and that the user can list the collections of the configured databases (a database the user cannot read is named in the error). A standalone server passes the test with a warning in the logs; only its Incremental syncs fail. Airbyte then discovers the collections and, when Schema Enforced is on, samples their documents to build the schema (see Schema Enforcement); on a cluster with many collections this can take a few minutes.
Step 4: Allow inbound traffic from Airbyte
If your cluster only accepts connections from known addresses, allow Airbyte's:
- Airbyte Cloud: add the Airbyte Cloud IP addresses to your allow list. On Atlas, that is Network Access under Security.
- Self-managed Airbyte: allow the addresses of the machines or Kubernetes nodes that run your Airbyte workers.
Replication Methods
Each collection is a stream that can be synced in Full Refresh or Incremental mode.
Full Refresh
A full refresh reads the whole collection, ordered by _id, on every sync. The read is checkpointed as it goes, about every gigabyte of documents: a sync that fails part way through (because of a network error, for example) continues from the last checkpointed _id instead of starting over.
Incremental (CDC)
An incremental sync has two phases:
- Initial snapshot. The first sync reads the whole collection, ordered by
_idand checkpointed as above. Before the snapshot starts, the connector records the current position of the change stream, so changes made during a long initial load are not lost: they are replayed by the next sync. - Change streams. Later syncs resume the change stream from the saved position and emit every insert, update,
replace and delete made up to the moment the sync started. An update record carries the document as it is when the
event is read (MongoDB's
updateLookup), so several updates in quick succession can all show the final state; changes made while the sync runs are picked up by the next one, so a busy cluster cannot keep a sync open indefinitely. Deletes are emitted as records with_ab_cdc_deleted_atset; they carry the deleted document when the collection stores pre-images (MongoDB 6.0 or later), and only its_idotherwise. An update to a document that was deleted before the connector could read it back is emitted as a delete.
To learn how Airbyte implements CDC in general, refer to Change Data Capture (CDC).
Change streams are built on the replica set oplog, which only retains a limited window of changes. If the saved position is no longer in the oplog, the sync either fails or starts over, as chosen by the Invalid CDC position behavior setting. Long initial snapshots are protected automatically: a snapshot that runs longer than 8 hours pauses, its progress is saved and the sync is retried, and the retry reads the change stream before resuming the snapshot where it left off. See MongoDB Oplog and Change Streams for how to size the oplog.
Every record of an incremental stream carries three metadata fields: _ab_cdc_updated_at (the change time of a
change-stream event, or the sync time for a snapshot row), _ab_cdc_deleted_at (set for deletes) and _ab_cdc_cursor
(the stream's cursor: the oplog time of a change event, or the change-stream position the sync saved for a snapshot
row, so a later change always supersedes the row it replaces).
Requirements on the _id field
The connector orders and resumes reads by _id, so:
- Use one BSON type for
_idthroughout a collection. Integers, longs, doubles and decimals count as one type. MongoDB sorts_ids by type before value, and a read resumed from a checkpoint continues with the checkpointed type only. A collection that mixes types — for example integer and string_ids — is read in full as long as the read is not interrupted, but after a checkpoint the documents of the other types are not synced. When such a collection's read starts, the connector logsThe _id fields in this collection are not consistently typed, which may lead to data losswith the types it found. Make the_idtype consistent or exclude the collection from the connection. - Checkpoints are exact for every
_idtype:ObjectId, string, integer, long, double, decimal, date, timestamp, binary (UUIDs included), embedded document and the remaining BSON types.
Schema Enforcement
By default the connector enforces a schema: when the source is set up (and whenever you refresh the source schema) it samples a configurable number of documents from each collection, collects their top-level fields and infers each field's type. You can then deselect fields in the connection's replication settings. Only the fields in the schema are read from the server.
The schema is inferred, not declared, so keep in mind:
- A field that is missing from the sampled documents is not in the schema and is not synced until you refresh the schema.
- When a field holds different types in different documents, the schema uses the type seen first. Values are emitted in their own type regardless (a string stays a string even in a field typed
number), but typed destinations may not accept such a value, in which case it arrives asnull. Collections like this are better synced in schemaless mode. - Empty collections have no fields to sample and are not discovered.
- Views and time series collections are not synced and are not discovered: MongoDB provides no change streams for either, and a time series collection has no
_idindex to checkpoint and resume a snapshot from. For a view, sync the underlying collection instead.
When Schema Enforced is off, collections are read in schemaless mode, which does not assume documents share a structure. Each document produces a record with exactly two top-level fields:
{
  "_id": <document id>,
  "data": {<the whole document, _id included>}
}
The contents of data vary with each document: no field is omitted and no document is rejected, so a field may be a string in one record and an object in the next. Fields cannot be deselected in schemaless mode. Schema discovery is lighter in this mode: the sample is only used to find the type of _id.
Array Type Normalization
Most destinations can safely cast between primitive types (for example, integer to string), but they cannot reconcile composite types such as an object versus an array. Without normalization, records with such a mismatch would be written as NULL in the destination. In schema-enforced mode the connector therefore wraps any non-array value of a field whose schema type is array in a one-element array.
// Document 1 - Array (matches schema)
{ "reviews": [{"rating": "A"}, {"rating": "B"}] }

// Document 2 - Single object (auto-wrapped)
{ "reviews": {"rating": "A"} }  →  { "reviews": [{"rating": "A"}] }
This normalization is intended for occasional type inconsistencies. If your collection has fields that frequently change types, consider using schemaless mode instead.
Data Type Mapping
BSON types are mapped to the following Airbyte types in the discovered schema, and their values are emitted as described in the notes. The same conversions apply inside data in schemaless mode and inside nested documents and arrays.
MongoDB Data Type Mapping
| BSON type | Resulting type | Notes |
|---|---|---|
objectId | string | 24-character hexadecimal string |
string | string | |
bool | boolean | |
int, long | number | Emitted as JSON numbers without a fractional part |
double | number | Emitted as a JSON number; NaN and the infinities, which JSON has no number for, as the strings NaN, Infinity and -Infinity |
decimal | number | Emitted with its full precision; NaN and the infinities as the strings NaN, Infinity and -Infinity |
date | string | ISO 8601 in UTC with milliseconds, e.g. 2024-01-01T00:00:00.000Z |
timestamp | string | MongoDB's internal timestamp. Its 64-bit value is rendered as an ISO 8601 date-time as if it were milliseconds since the epoch, which produces a far-future date; this is kept for backward compatibility. Use a date field to store points in time. |
binData | string | Base64 encoding of the bytes, for every subtype (UUIDs included) |
regex | string | (options)pattern, or just the pattern when there are no options |
javascript | string | The code |
javascriptWithScope | object | {"code": <code>, "scope": <scope document>} |
symbol | string | |
object | object | The embedded document, converted with the same rules |
array | array | Elements converted with the same rules; the schema does not declare an element type |
null | null | |
minKey, maxKey, undefined, dbPointer | — | Not synced: the value is omitted from data and nested documents, and null in schema-enforced mode |
Limitations & Troubleshooting
To see connector limitations, or troubleshoot your MongoDB connector, see more in our MongoDB troubleshooting guide.
Schema discovery performance impact
Schema discovery runs aggregation queries against your MongoDB cluster in parallel across all collections of a database. On production clusters with many collections or large documents, this can cause significant resource pressure, including degraded query performance, replication lag, or in extreme cases, cluster instability.
Because MongoDB collections are schemaless, no sample size can guarantee a complete or stable schema — new fields can appear in documents at any time. When schema enforcement is enabled, the connector's Discover phase runs $sample aggregation pipelines against every collection in the configured databases in parallel. On clusters with many collections or large documents, these concurrent queries can cause significant resource pressure on your MongoDB deployment, including degraded performance or cluster instability.
For recommended approaches and other alternatives to protect your production cluster, see Schema discovery performance impact in the troubleshooting guide.
MongoDB CDC Limitations
MongoDB has a 16MB maximum document size limit for BSON documents. During CDC syncs, change stream events can exceed this limit when documents are large, causing a BSONObjectTooLarge error. For details on resolving this error, see the MongoDB CDC Limitations section in the troubleshooting guide.
Configuration Parameters
| Parameter Name | Description |
|---|---|
| Cluster Type | Whether the cluster is hosted on MongoDB Atlas or self-hosted. Connections to Atlas always use TLS and require a username and password. |
| Connection String | The connection string of the source MongoDB cluster. For Atlas hosted clusters, see the quick start guide for steps to find the connection string. For self-hosted clusters, refer to the MongoDB connection string documentation. Connection string options such as tls and readPreference are honored. |
| Database Names | The names of the MongoDB databases that contain the collections to sync. Configuring more than one database requires readAnyDatabase privileges (see Step 1). |
| Username | The username which is used to access the database. Required for MongoDB Atlas clusters. |
| Password | The password associated with this username. Required for MongoDB Atlas clusters. |
| Schema Enforced | Controls whether a schema is discovered and enforced. Defaults to on. See Schema Enforcement. |
| Document discovery sample size (Advanced) | The maximum number of documents to sample per collection when discovering its fields. Default is 10,000 with a valid range of 10 to 100,000. See the MongoDB sampling method for more details. |
| Invalid CDC position behavior (Advanced) | What to do when the saved change stream position is no longer valid, usually because the oplog no longer contains it. If "Fail sync" is chosen, the sync fails until you refresh the connection (a refresh takes a new initial snapshot; choose whether to keep or remove the existing records) or clear it. If "Re-sync data" is chosen, the connector discards the saved position and snapshot progress and takes a new initial snapshot, which increases cost and misses the changes that occurred while the position was invalid. Default is "Fail sync". |
Reference
Config fields reference
Changelog
Expand to review
| Version | Date | Pull Request | Subject |
|---|---|---|---|
| 3.0.1 | 2026-10-28 | 90162 | Hide auth_source from the setup form; it defaults to admin when not set. |
| 3.0.0 | 2026-10-27 | 89773 | Rewrite on the Bulk CDK: change streams are read with the MongoDB driver instead of Debezium; existing connections upgrade in place; no clear or refresh needed. Docker image renamed from airbyte/source-mongodb-v2 to airbyte/source-mongodb. Views and time series collections are no longer discovered; booleans typed as boolean; decimals keep full precision; initial_waiting_seconds, queue_size and update_capture_mode removed. See the migration guide. |
| 2.1.1 | 2026-09-26 | 87019 | Harden initial load iterator: surface sub-query failures instead of silently ending the stream, and fail with the intended transient error on CDC initial-load timeout. |
| 2.1.0 | 2026-09-02 | 83705 | Support sharded clusters and object-type _id fields; detect _id types with index seeks instead of a full collection scan; bump Debezium to 3.6.2 and base image to 2.0.4 |
| 2.0.7 | 2026-01-21 | 71049 | Use debezium's own token validation logic to ensure that the saved resume token is present on the server (h/t @ed-kyu) |
| 2.0.6 | 2026-01-21 | 70980 | Convert non-array MongoDB values into arrays when the schema expects an array to prevent nulls. |
| 2.0.5 | 2026-01-14 | 71255 | fix(source-mongodb-v2): Add helpful error message for BSONObjectTooLarge errors during CDC syncs |
| 2.0.4 | 2025-09-10 | 65579 | Add validation to ensure state format consistency. |
| 2.0.3 | 2025-08-12 | 64900 | Fix hardcoded read preferences to allow specification in connection string. |
| 2.0.2 | 2025-07-14 | 62938 | Only require a single database read permission when configured to sync a single database. |
| 2.0.1 | 2025-06-04 | 61369 | Do not pin on 1.5.17 |
| 2.0.0 | 2025-05-27 | 60252 | Add support for multiple databases |
| 1.5.19 | 2025-05-15 | 60311 | Migrate to new Gradle flow |
| 1.5.18 | 2025-04-24 | 58132 | Fix vulnerabilities in dependencies. |
| 1.5.17 | 2025-04-17 | 58111 | Implement timeout for document discovery |
| 1.5.16 | 2025-04-02 | 56973 | Update logging configuration. |
| 1.5.15 | 2025-03-06 | 55234 | Update base image version for certified DB source connectors |
| 1.5.14 | 2025-01-10 | 51491 | Use a non root base image |
| 1.5.13 | 2024-12-18 | 49868 | Use a base image: airbyte/java-connector-base:1.0.0 |
| 1.5.12 | 2024-11-01 | 48115 | Remove database name check. |
| 1.5.11 | 2024-09-24 | 45883 | Lazy init mongocursor to prevent timeout. |
| 1.5.10 | 2024-09-17 | 45639 | Adopt latest CDK to use the latest apache sshd mina to handle tcpkeepalive requests. |
| 1.5.9 | 2024-08-28 | 42927 | Support binary subtype. |
| 1.5.8 | 2024-08-27 | 44841 | Adopt latest CDK. |
| 1.5.7 | 2024-08-27 | 44846 | DBZ filters in related streams only. |
| 1.5.6 | 2024-08-27 | 44839 | DBZ filters in related streams only. |
| 1.5.5 | 2024-08-26 | 44779 | Revert permission check on oplog.rs. |
| 1.5.4 | 2024-08-20 | 44490 | Add read permission check on oplog.rs collection used by CDC. |
| 1.5.3 | 2024-08-08 | 43410 | Adopt latest CDK. |
| 1.5.2 | 2024-08-06 | 42869 | Adopt latest CDK. |
| 1.5.1 | 2024-08-01 | 42549 | Centered the connector icon. |
| 1.5.0 | 2024-07-26 | 42561 | Implement WASS algorithm. |
| 1.4.3 | 2024-07-22 | 39145 | Warn (vs fail) on different _id types in collection. |
| 1.4.2 | 2024-07-01 | 40516 | Remove dbz hearbeat. |
| 1.4.1 | 2024-06-11 | 39530 | Adopt new CDK. |
| 1.4.0 | 2024-06-11 | 38238 | Update mongodbv2 to use dbz 2.6.2 |
| 1.3.15 | 2024-05-30 | 38781 | Sync sending trace status messages indicating progress. |
| 1.3.14 | 2024-05-29 | 38584 | Set is_resumable flag in discover. |
| 1.3.13 | 2024-05-09 | 36851 | Support reading collection with a binary _id type. |
| 1.3.12 | 2024-05-07 | 36851 | Upgrade debezium to version 2.5.1. |
| 1.3.11 | 2024-05-02 | 37753 | Chunk size(limit) should correspond to ~1GB of data. |
| 1.3.10 | 2024-05-02 | 37781 | Adopt latest CDK. |
| 1.3.9 | 2024-05-01 | 37742 | Adopt latest CDK. Remove Debezium retries. |
| 1.3.8 | 2024-04-24 | 37559 | Implement fixed-size chunking while performing initial load. |
| 1.3.7 | 2024-04-24 | 37557 | Change bug in resume token validity check. |
| 1.3.6 | 2024-04-24 | 37525 | Internal refactor. |
| 1.3.5 | 2024-04-22 | 37348 | Do not send estimate trace if we do not have data. |
| 1.3.4 | 2024-04-16 | 37348 | Populate null values in airbyte record messages. |
| 1.3.3 | 2024-04-05 | 36872 | Update to connector's metadat definition. |
| 1.3.2 | 2024-04-04 | 36845 | Adopt Kotlin CDK. |
| 1.3.1 | 2024-04-04 | 36837 | Adopt CDK 0.28.0. |
| 1.3.0 | 2024-03-15 | 35669 | Full refresh read of collections. |
| 1.2.16 | 2024-03-06 | 35669 | State message will now include record count. |
| 1.2.15 | 2024-02-27 | 35673 | Consume user provided connection string. |
| 1.2.14 | 2024-02-27 | 35675 | Fix invalid cdc error message. |
| 1.2.13 | 2024-02-22 | 35569 | Fix logging bug. |
| 1.2.12 | 2024-02-21 | 35526 | Improve error handling. |
| 1.2.11 | 2024-02-20 | 35375 | Add config to throw an error on invalid CDC position and enable it by default. |
| 1.2.10 | 2024-02-13 | 34751 | Emit analytics message for invalid CDC cursor. |
| 1.2.9 | 2024-02-13 | 35114 | Extend subsequent cdc record wait time to the duration of initial. Bug Fixes |
| 1.2.8 | 2024-02-08 | 34748 | Adopt CDK 0.19.0 |
| 1.2.7 | 2024-02-01 | 34759 | Fail sync if initial snapshot for any stream fails. |
| 1.2.6 | 2024-01-31 | 34594 | Scope initial resume token to streams of interest. |
| 1.2.5 | 2024-01-29 | 34641 | Allow resuming an initial snapshot when Id type is not of default ObjectId . |
| 1.2.4 | 2024-01-26 | 34573 | Adopt CDK v0.16.0. |
| 1.2.3 | 2024-01-18 | 34364 | Add additional logging for resume token + reduce discovery size to 10. |
| 1.2.2 | 2024-01-16 | 34314 | Reduce minimum document discovery size to 100. |
| 1.2.1 | 2023-12-18 | 33549 | Add logging to understand op log size. |
| 1.2.0 | 2023-12-18 | 33438 | Remove LEGACY state flag |
| 1.1.0 | 2023-12-14 | 32328 | Schema less mode in mongodb. |
| 1.0.12 | 2023-12-13 | 33430 | Add more verbose logging. |
| 1.0.11 | 2023-11-28 | 33356 | Support for better debugging tools. |
| 1.0.10 | 2023-11-28 | 32886 | Handle discover phase OOMs |
| 1.0.9 | 2023-11-08 | 32285 | Additional support to read UUIDs |
| 1.0.8 | 2023-11-08 | 32125 | Fix compilation warnings |
| 1.0.7 | 2023-11-07 | 32250 | Add support to read UUIDs. |
| 1.0.6 | 2023-11-06 | 32193 | Adopt java CDK version 0.4.1. |
| 1.0.5 | 2023-10-31 | 32028 | url encode username and password. Handle a case of document update and delete in a single sync. |
| 1.0.3 | 2023-10-19 | 31629 | Allow discover operation use of disk file when an operation goes over max allowed mem |
| 1.0.2 | 2023-10-19 | 31596 | Allow use of temp disk file when an operation goes over max allowed mem |
| 1.0.1 | 2023-10-03 | 31034 | Fix field filtering logic related to nested documents |
| 1.0.0 | 2023-10-03 | 29969 | General availability release using Change Data Capture (CDC) |
| 0.2.5 | 2023-07-27 | 28815 | Revert back to version 0.2.0 |
| 0.2.4 | 2023-07-26 | 28760 | Fix bug preventing some syncs from succeeding when collecting stats |
| 0.2.3 | 2023-07-26 | 28733 | Fix bug preventing syncs from discovering field types |
| 0.2.2 | 2023-07-25 | 28692 | Fix bug preventing statistics retrieval from views |
| 0.2.1 | 2023-07-21 | 28527 | Log server information |
| 0.2.0 | 2023-06-26 | 27737 | License Update: Elv2 |
| 0.1.19 | 2022-10-07 | 17614 | Increased discover performance |
| 0.1.18 | 2022-10-05 | 17590 | Add ability to enforce SSL in MongoDB connector and check logic |
| 0.1.17 | 2022-09-08 | 16401 | Fixed bug with empty strings in fields with aibyte_transform |
| 0.1.16 | 2022-08-18 | 14356 | DB Sources: only show a table can sync incrementally if at least one column can be used as a cursor field |
| 0.1.15 | 2022-06-17 | 13864 | Updated stacktrace format for any trace message errors |
| 0.1.14 | 2022-05-05 | 12428 | JsonSchema: Add properties to fields with type 'object' |
| 0.1.13 | 2022-02-21 | 10276 | Create a custom codec registry to handle DBRef MongoDB objects |
| 0.1.12 | 2022-02-14 | 10256 | (unpublished) Add -XX:+ExitOnOutOfMemoryError JVM option |
| 0.1.11 | 2022-01-10 | 9238 | Return only those collections for which the user has privileges |
| 0.1.10 | 2021-12-30 | 9202 | Update connector fields title/description |
| 0.1.9 | 2021-12-07 | 8491 | Configure 10000 limit doc reading during Discovery step |
| 0.1.8 | 2021-11-29 | 8306 | Added milliseconds for date format for cursor |
| 0.1.7 | 2021-11-22 | 8161 | Updated Performance and updated cursor for timestamp type |
| 0.1.5 | 2021-11-17 | 8046 | Added milliseconds to convert timestamp to datetime format |
| 0.1.4 | 2021-11-15 | 7982 | Updated Performance |
| 0.1.3 | 2021-10-19 | 7160 | Fixed nested document parsing |
| 0.1.2 | 2021-10-07 | 6860 | Added filter to avoid MongoDb system collections |
| 0.1.1 | 2021-09-21 | 6364 | Source MongoDb: added support via TLS/SSL |
| 0.1.0 | 2021-08-30 | 5530 | New source: MongoDb ported to java |